
What is MiMo-V2.6-Flash?
MiMo-V2.6-Flash is the smaller model in Xiaomi's V2.6 series: a mixture-of-experts model with 309B parameters, 15B of them active for each token, that reads text, images, video and audio and writes text. It went through the same large reinforcement learning run as MiMo-V2.6-Pro, and Xiaomi says it now beats MiMo-V2.5-Pro across the board.
It is Xiaomi's current low-cost model, sold at the price of the MiMo-V2.5 it replaces. Early users hit repeated tool calls in agents; Xiaomi cut them sharply with an update on its API under the same name and published the updated weights as MiMo-V2.6-Flash-MOPD.
What changed from MiMo-V2-Flash?
Same size, far more reach: it keeps the 309B design but reads images, video and audio, holds four times the context, and replaces a model Xiaomi no longer serves.
- Size
- Still 309B parameters with 15B active per token.
- Context
- 1M tokens, up from 256K.
- Input
- Text, images, video and audio; MiMo-V2-Flash read text only.
- Training
- It went through Xiaomi's large V2.6 reinforcement learning run across coding, agent, visual and security tasks.
- Availability
- Xiaomi's API no longer serves mimo-v2-flash; calls now need mimo-v2.6-flash.
Who is MiMo-V2.6-Flash best for?
MiMo-V2.6-Flash suits high-volume agent and coding jobs, cheap work with screens, video and audio, self-hosting on one large server, and Token Plan subscribers.
High-volume agent and coding jobs
It costs $0.14 / $0.28 per million tokens, and half that on the Batch API, for runs that make many calls.
Screens, video and audio on a budget
It reads all four input types in one model and scored 80.8 on OSWorld-Verified for computer use, by Xiaomi's measure.
Self-hosting on one large server
The MIT-licensed weights take about 178 GB, and Xiaomi's vLLM recipe runs them across four GPUs.
Token Plan subscribers
Flash uses a third of the credits Pro does, so the $6 Lite plan covers about 200 rounds of medium-to-complex tasks.
What's included with MiMo-V2.6-Flash?
Four input types, a 1M context, fast multi-token decoding, half-price batch jobs, tools and web search, and credit plans for coding tools.
- Four input types
- Text, images, video and audio go into one model, with a 1M-token context and up to 128K tokens out.
- Fast decoding
- A five-layer multi-token drafter predicts seven tokens per pass to speed up output.
- Batch API
- Half-price input and output, $0.07 / $0.14 per million tokens, for jobs that can wait.
- Thinking, tools and web search
- Deep thinking, function calls, structured output, streaming and a web search plugin at $5 per 1,000 calls.
- Token Plan for coding tools
- Monthly credit plans from $6 work in Claude Code, Codex, OpenCode and OpenClaw.
- Updated checkpoint to download
- The MiMo-V2.6-Flash-MOPD weights carry Xiaomi's update that cuts repeated tool calls.
How much does MiMo-V2.6-Flash cost?
MiMo-V2.6-Flash costs $0.14 per million input tokens and $0.28 per million output tokens on Xiaomi's API, the weights are free, and Token Plans start at $6 a month.
- MIT licence, commercial use allowed
- About 178 GB of weights on Hugging Face
- The MOPD checkpoint cuts repeated tool calls
- Cache hits $0.0028 per million input tokens
- Batch API: $0.07 / $0.14
- Web search $5 per 1,000 calls
- 4.1 billion credits a month
- Flash uses 100 credits per input token, 200 per output token
- About 200 rounds of medium-to-complex tasks
- 11 billion credits a month
- About 1,600 rounds of medium-to-complex tasks
- No five-hour or weekly caps
Token Plan Pro and Max cost $50 and $100 a month; yearly billing is 12% cheaper, and usage between 16:00 and 24:00 UTC counts at 0.8x. These are Xiaomi's overseas prices in US dollars; mainland China prices are in yuan. Full pricing on mimo.mi.com. We checked these prices on .
How do readers rate MiMo-V2.6-Flash?
No one has rated MiMo-V2.6-Flash yet. Be the first.
Sign in to rate. One rating per account.
MiMo-V2.6-Flash pros and cons
It is very cheap and light enough to host, but early users hit loops and heavy overthinking, and many rate DeepSeek V4.1 Flash better on hard tasks.
Pros
- Very cheap to run: users describe the API price as extremely low, and several found it cheaper than DeepSeek V4.1 Flash for the same work.
- Small enough for a large workstation or a small cluster at about 178 GB, and users report running it on their own hardware.
- Handles simpler coding jobs well: several users say it crushes easy tasks and matches DeepSeek on code quality.
- Xiaomi's own table has it ahead of MiMo-V2.5-Pro on every test where both have a score, 67.9 against 19.0 on DeepSWE v1.1.
Cons
- Looped in agents at launch: many users saw it rerun the same commands until stopped; Xiaomi confirmed the problem and says an update on its API cut it sharply, and later users say the loops stopped.
- Overthinks: users report pages of reasoning for simple prompts, sometimes more than Pro, which costs time and tokens.
- Several users rate DeepSeek V4.1 Flash clearly better once tasks get complex.
- Weak on harder security work: Xiaomi's own table shows 25.3 on ExploitBench against 47.9 for Pro and 70.0 for Claude Opus 5.
Is MiMo-V2.6-Flash open source?
Yes. MiMo-V2.6-Flash's code is public under the MIT licence, so you can run it on your own server.
What are the best MiMo-V2.6-Flash alternatives?
MiMo-V2.6-Flash is an open source alternative to Mistral Medium 3.5, Gemini 3.8 Flash and GPT-6 Luna. DeepSeek V4.1 Flash, Bonsai 27B and Step-3.5-Flash do the same job and are open source too.
 Mistral Medium 3.5Free
Mistral's 128B open-weight model for coding agents and reasoning, with a 256K-token context.
 Gemini 3.8 FlashFree
Google's Gemini 3.8 Flash for coding, reasoning and agents.
 GPT-6 LunaFree
OpenAI's lowest cost GPT-6 model for focused, high volume tasks.
 DeepSeek V4.1 FlashOpen Source
Choose it when harder agent tasks matter more than the lowest price; it costs $0.30 / $1.20 per million tokens at peak and half that off-peak, with a 1M context and image input.
 Bonsai 27BOpen Source
PrismML's 1-bit and ternary 27B models that run locally on modest hardware.
 Step-3.5-FlashOpen Source
StepFun's 196B MoE with a 256K context for coding and agents.
Questions about MiMo-V2.6-Flash
What is the difference between MiMo-V2.6-Flash-RL and MiMo-V2.6-Flash-MOPD?
They are two checkpoints of the same model. RL is the launch version; MOPD is a later update Xiaomi trained to stop the model repeating the same tool calls, and Xiaomi's API now serves the updated model under the mimo-v2.6-flash name.
Who is MiMo-V2.6-Flash for?
MiMo-V2.6-Flash suits high-volume agent and coding jobs, cheap work with screens, video and audio, self-hosting on one large server, and Token Plan subscribers.
Is MiMo-V2.6-Flash free?
The weights are free to download under the MIT licence. Xiaomi's API is paid, at $0.14 per million input tokens and $0.28 per million output tokens, and Token Plans that cover it start at $6 a month.
How much does MiMo-V2.6-Flash cost?
MiMo-V2.6-Flash's paid plans are Pay-as-you-go API at $0.14 / $0.28 per million input / output tokens, Token Plan Lite at $6 per month and Token Plan Standard at $16 per month.
Is MiMo-V2.6-Flash open source?
Yes. MiMo-V2.6-Flash's code is public under the MIT licence, so you can run it on your own server.
What are the best MiMo-V2.6-Flash alternatives?
The closest alternatives on Recaply are Mistral Medium 3.5, Gemini 3.8 Flash, GPT-6 Luna, DeepSeek V4.1 Flash, Bonsai 27B and Step-3.5-Flash.
Where can I try MiMo-V2.6-Flash?
On its official website, huggingface.co.
Can I run MiMo-V2.6-Flash locally?
On a large machine, yes. The weights take about 178 GB, and Xiaomi's vLLM recipe runs them across four GPUs. Download the MiMo-V2.6-Flash-MOPD checkpoint, which carries Xiaomi's update against repeated tool calls.
MiMo-V2.6-Flash or MiMo-V2.6-Pro: which should I use?
Start with Flash for high-volume or simple tasks: it costs about a third as much and trails Pro by four points on DeepSWE v1.1. Move to Pro for long, hard or security work, where Xiaomi's own table shows a wider gap.
Our verdict
MiMo-V2.6-Flash is a very cheap open model for volume work, but test it hard before you trust it with complex agent runs.
It costs $0.14 / $0.28 per million tokens and beats MiMo-V2.5-Pro on Xiaomi's tests, but early users hit loops and heavy overthinking, and many prefer DeepSeek V4.1 Flash once tasks get hard.
- Skip it for
- Complex or security-heavy agent work, where MiMo-V2.6-Pro or DeepSeek V4.1 Flash are safer picks.
- Check first
- If you self-host, use the MOPD weights, and watch reasoning length and repeated tool calls in your own harness.
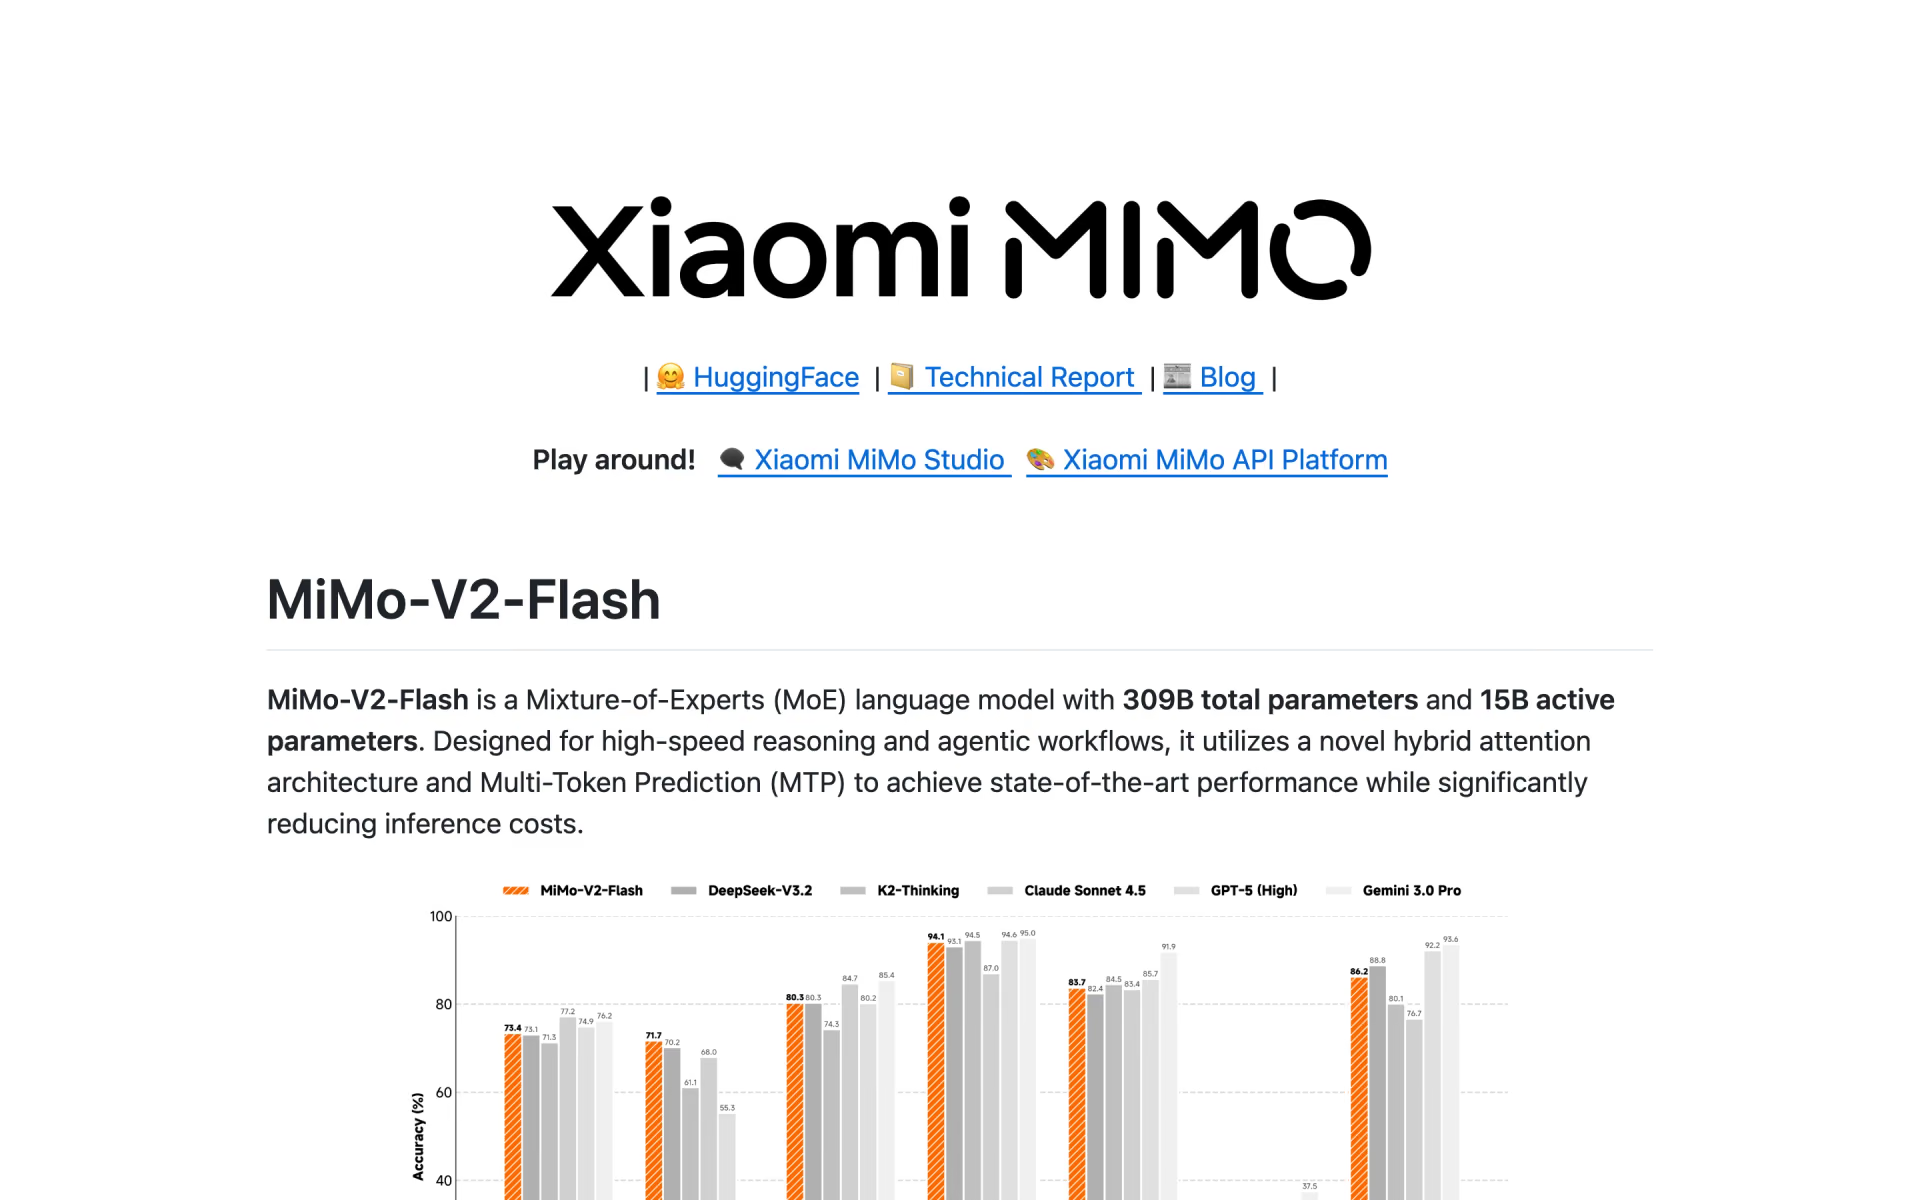
 MiMo-V2-Flash

 MiMo-V2.6-Pro
 Step 3.7 Flash
 Qwen3.8-Flash
 DeepSeek-V3.2
 Gemini 3.5 Flash