
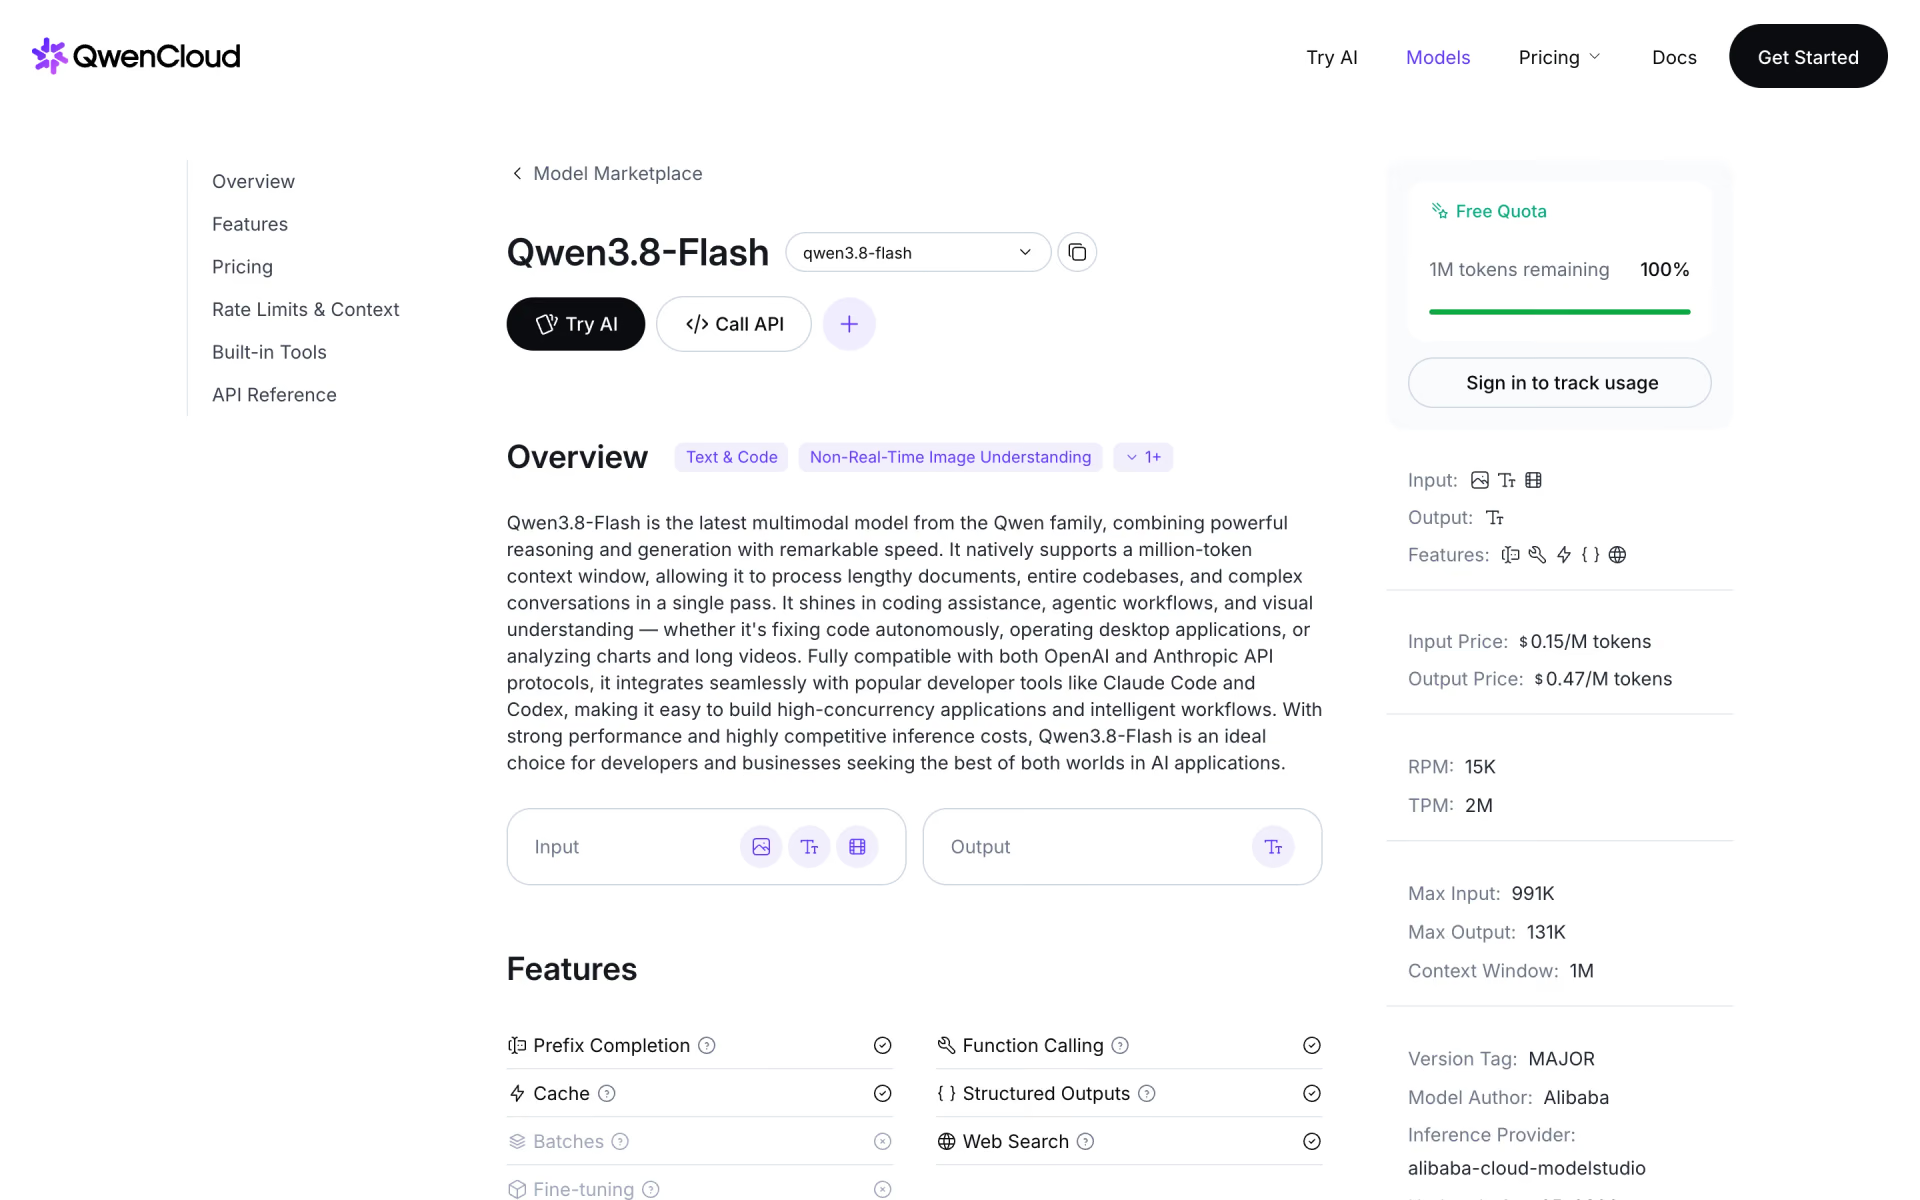
What is Qwen3.8-Flash?
Qwen3.8-Flash reads text, images and video, holds 1M tokens and thinks before it answers, at three effort levels. On Qwen Cloud it comes with built-in tools such as web search, a code interpreter and PDF parsing, and it speaks both OpenAI and Anthropic API formats, so it drops into Claude Code or Codex.
It is the production version of Qwen3.8-Flash-Next, an open-weight preview of the Qwen4 design with 125B parameters, 6B active per token, plus a 51B lookup table. Alibaba scores it above Qwen3.7-Plus on coding and office tests at under half the price. It is not in the free Qwen Chat app.
Who is Qwen3.8-Flash best for?
Qwen3.8-Flash is best for high-volume agents, coding in Claude Code or Codex, phone and desktop agents, and long documents or video on a tight budget.
High-volume agents and subagents
At $0.15 / $0.47 per million tokens, with cached input at $0.016, it sits in Qwen Cloud's lightweight, low-cost tier.
Coding in Claude Code or Codex
Alibaba documents both setups, and the open model it is built on scores 62.5% on SWE-bench Pro, above Qwen3.8-27B and Qwen3.7-Plus.
Phone and desktop agents
The open model it is built on scores 84.5 on AndroidWorld in Alibaba's tests, and it reads screenshots and video to decide what to do next.
Long documents and video
It holds 1M tokens by default and takes image and video input, with PDF parsing built in on Qwen Cloud.
What's included with Qwen3.8-Flash?
Built-in web search, code interpreter and PDF parsing, three thinking levels, cheap context caching, half-price batch calls, OpenAI and Anthropic compatible APIs, and fine-tuning.
- Built-in tools
- Web search, web extraction, code interpreter and image search through the Responses API, PDF parsing through Completions, and web fetch through the Anthropic API.
- Thinking control
- Reasoning effort at xhigh, medium or low, with xhigh as the default, and thinking can be turned off per request.
- Context caching
- Repeated prompt prefixes are billed at $0.016 per million tokens, about a tenth of the normal input rate.
- Batch calls
- Jobs that can wait run at half the real-time price.
- OpenAI and Anthropic compatible
- Chat Completions, Responses and Anthropic-style endpoints, with function calling and structured JSON output.
- Fine-tuning
- Qwen Cloud lists fine-tuning on your own sample data for this model.
How much does Qwen3.8-Flash cost?
Qwen3.8-Flash costs $0.15 per million input tokens and $0.47 per million output tokens on Qwen Cloud, with 1M free tokens for new accounts; Token Plan starts at $8 a month.
- Qwen3.8-Flash-Next, the open model it is built on
- 262,144-token context, up to 1M with YaRN
- Qwen Community License, with extra terms for API hosts
- Cached input $0.016; batch calls half price
- 1M-token context, up to 131K tokens out
- 1M free tokens for new accounts, for about 90 days
- Lite: 11,500 credits a month
- Essential $16, Standard $25, Pro $80 a month
- Credits also cover Qwen3.8-Max and other models
Qwen Cloud is Qwen's official API and lists prices in US dollars. Alibaba Cloud Model Studio charges $0.113 / $0.382 per million tokens on its Global scope in US (Virginia), and $0.15 / $0.47 in Singapore, the only Model Studio region with a free quota. Thinking tokens are billed as output, web search costs $10 per 1,000 calls, and the free quota needs payment details and does not cover batch calls or tool fees. Token Plan credits per request depend on the model, tokens, thinking and tools. Qwen Chat does not offer Qwen3.8-Flash. Full pricing on qwencloud.com. We checked these prices on .
How do readers rate Qwen3.8-Flash?
No one has rated Qwen3.8-Flash yet. Be the first.
Sign in to rate. One rating per account.
Qwen3.8-Flash pros and cons
Users say it codes close to Claude Opus models at a very low price, but it reasons at length by default, is not in Qwen Chat, and its open weights are big and not Apache-licensed.
Pros
- Users on Hacker News and Reddit say it handles real coding and agent work close to Claude Opus models, from merging large forks to finding and fixing a regression.
- Very low price: Hacker News users call the cost of real jobs remarkable, one noting it undercuts DeepSeek's cheap Flash model, and it costs under half as much as Qwen3.7-Plus while scoring higher on Alibaba's tests.
- Several users running the open version say it reaches answers in far fewer tokens and much less time than Qwen3.8-27B.
- Reads images and video, holds 1M tokens by default and includes web search, code execution and PDF parsing on Qwen Cloud.
Cons
- It thinks at length on its default xhigh setting: users report overthinking loops and far more reasoning tokens than Claude Opus on hard tasks, and every thinking token is billed as output.
- Not in the free Qwen Chat app, and free API use is limited to 1M tokens for new accounts, for about 90 days, after you add payment details.
- The open weights are hard to run at home: users say even heavily quantised builds need 73 GB or more of memory because of the 51B lookup table, and the licence is not Apache or MIT.
- Output stops at about 131K tokens per response, about a third of DeepSeek V4.1 Flash's 384K.
What are the best Qwen3.8-Flash alternatives?
Two tools on Recaply do Qwen3.8-Flash's job. Both are open source, so you can run them on your own server.
 GLM-5.3-FlashOpen Source
Choose it when you want MIT-licensed weights or file input at a similar price: Z.ai charges $0.15 / $0.50 per million tokens for a 1M-context model that reads video, images and files.
 DeepSeek V4.1 FlashOpen Source
Choose it when you need long outputs or MIT weights: it writes up to 384K tokens per response and costs $0.15 / $0.60 off-peak, $0.30 / $1.20 at peak.
Questions about Qwen3.8-Flash
What is the difference between Qwen3.8-Flash and Qwen3.8-Flash-Next?
Qwen3.8-Flash-Next is the open-weight model: 262,144 tokens of context natively, up to 1M with YaRN. Qwen3.8-Flash is Alibaba's hosted production version of it, with 1M context by default and built-in tools on Qwen Cloud.
Who is Qwen3.8-Flash for?
Qwen3.8-Flash is best for high-volume agents, coding in Claude Code or Codex, phone and desktop agents, and long documents or video on a tight budget.
Is Qwen3.8-Flash free?
Not in Qwen Chat, which offers Qwen3.7-Plus, Qwen3.8-Max and Qwen3.8-Omni-Flash instead. On Qwen Cloud, new accounts get 1M free tokens for about 90 days. The open model it is built on, Qwen3.8-Flash-Next, is a free download.
How much does Qwen3.8-Flash cost?
Qwen3.8-Flash's paid plans are Qwen Cloud API at $0.15 / $0.47 per million input / output tokens and Token Plan at From $8 per month.
Is there an open source alternative to Qwen3.8-Flash?
Yes. GLM-5.3-Flash and DeepSeek V4.1 Flash are open source tools that do the same job, so you can run your own.
What are the best Qwen3.8-Flash alternatives?
The closest alternatives on Recaply are GLM-5.3-Flash and DeepSeek V4.1 Flash.
Where can I try Qwen3.8-Flash?
On its official website, qwencloud.com.
Can I use Qwen3.8-Flash in Claude Code?
Yes. Qwen Cloud supports the Anthropic API format, so you point Claude Code at Qwen Cloud's endpoint and set the model to qwen3.8-flash. Alibaba also documents a Codex setup through the Responses API.
How do I make Qwen3.8-Flash think less?
Set reasoning effort to medium or low instead of the default xhigh, or turn thinking off with enable_thinking set to false. Thinking tokens are billed at the $0.47 output rate, so lower effort also cuts cost.
Can I use Qwen3.8-Flash-Next commercially?
Yes, the Qwen Community License allows commercial use. Very large products must show the model name, and companies selling model APIs or coding and office assistants need a separate licence from Qwen.
Our verdict
Qwen3.8-Flash is one of the best-value hosted models for coding and agents, if you keep an eye on how long it thinks.
Users report near-Opus results on real coding work, Alibaba scores it above Qwen3.7-Plus at under half the price, and it reads images and video across 1M tokens.
- Skip it for
- Free chat use, since Qwen Chat does not offer it, or self-hosting on modest hardware, where Qwen3.8-27B is far easier to run.
- Check first
- Try medium reasoning effort on your own tasks, since the default xhigh can multiply output tokens.

 Qwen3.6-Plus

 Qwen3.7-Plus
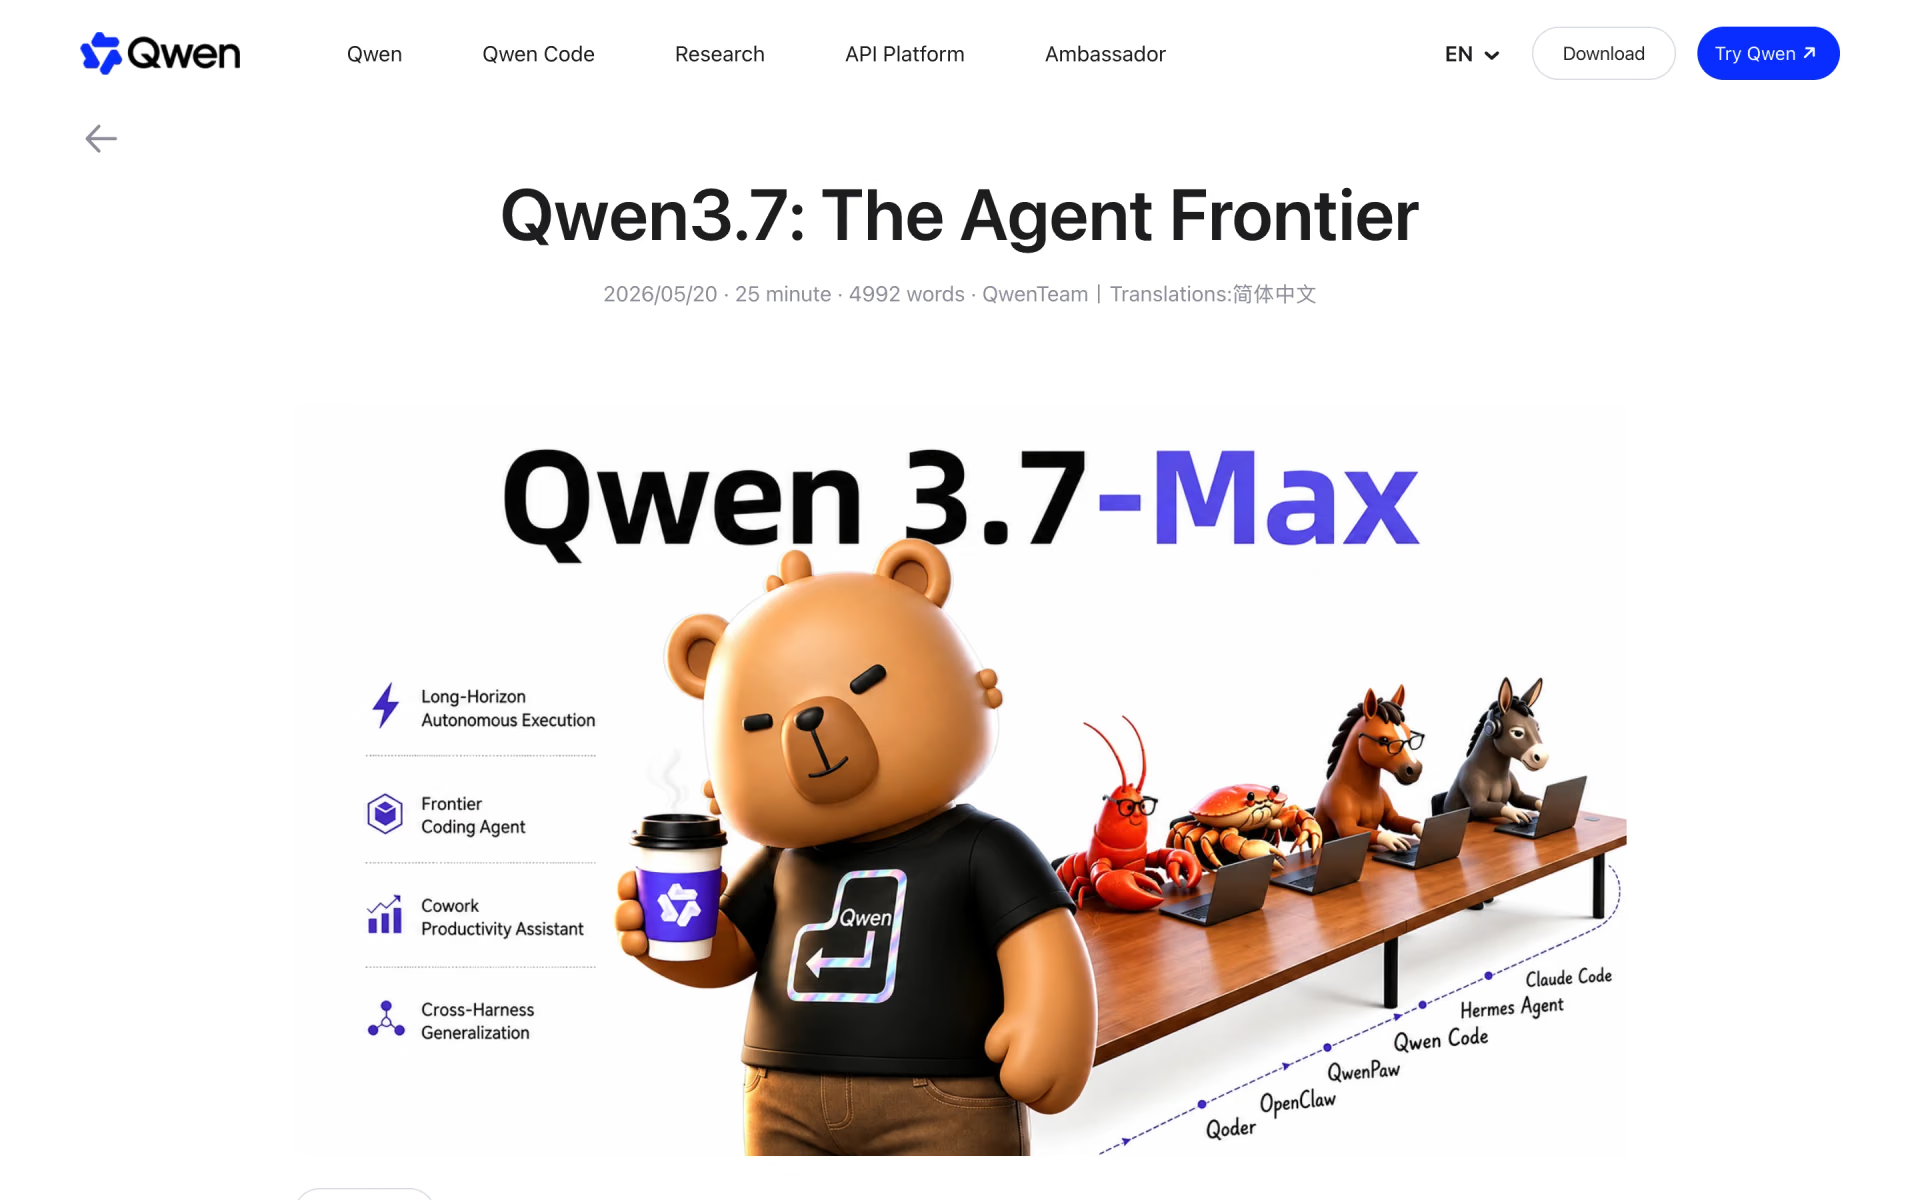
 Qwen3.7-Max
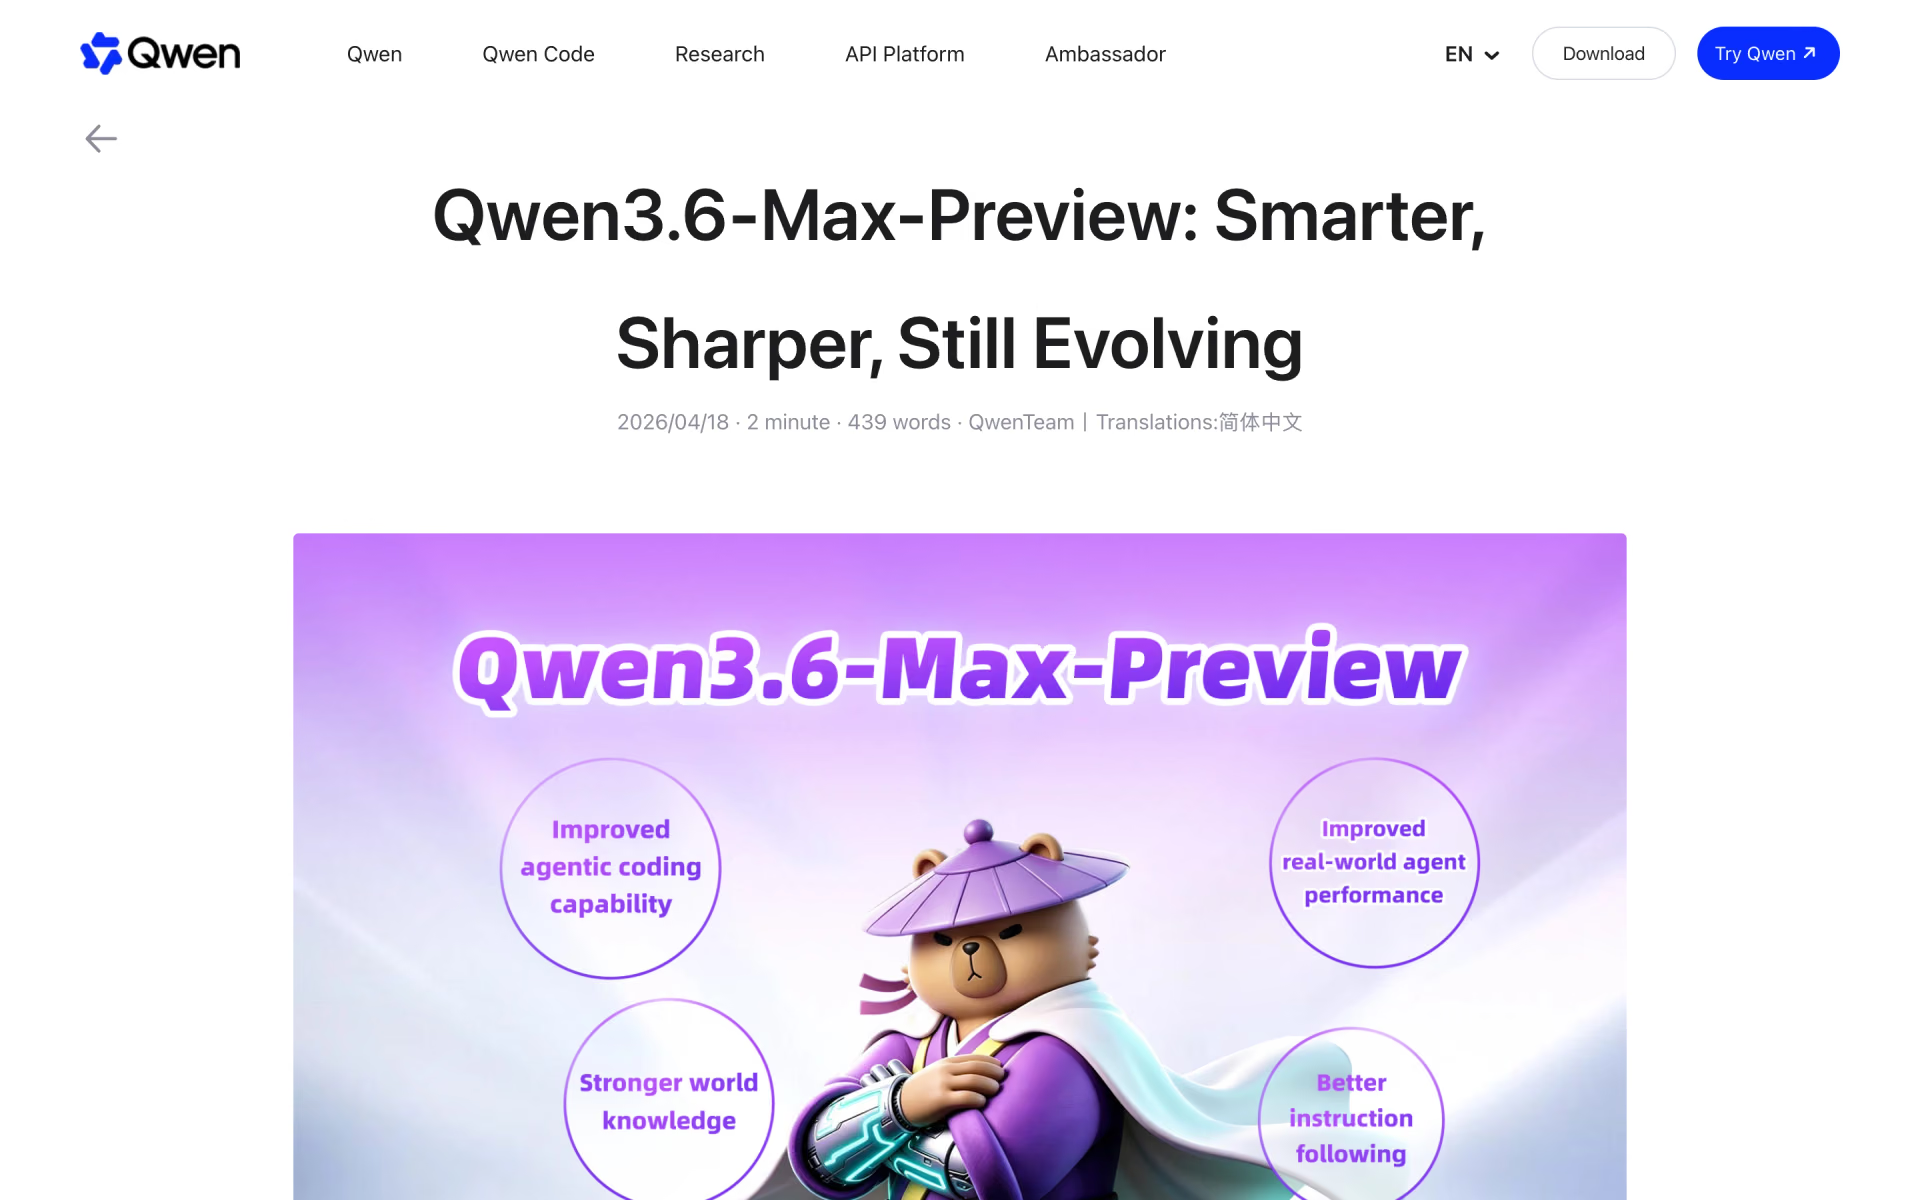
 Qwen3.6-Max-Preview
 Qwen3.8-Max
 Qwen3.5 Small