What is Qwen3.5-Omni?
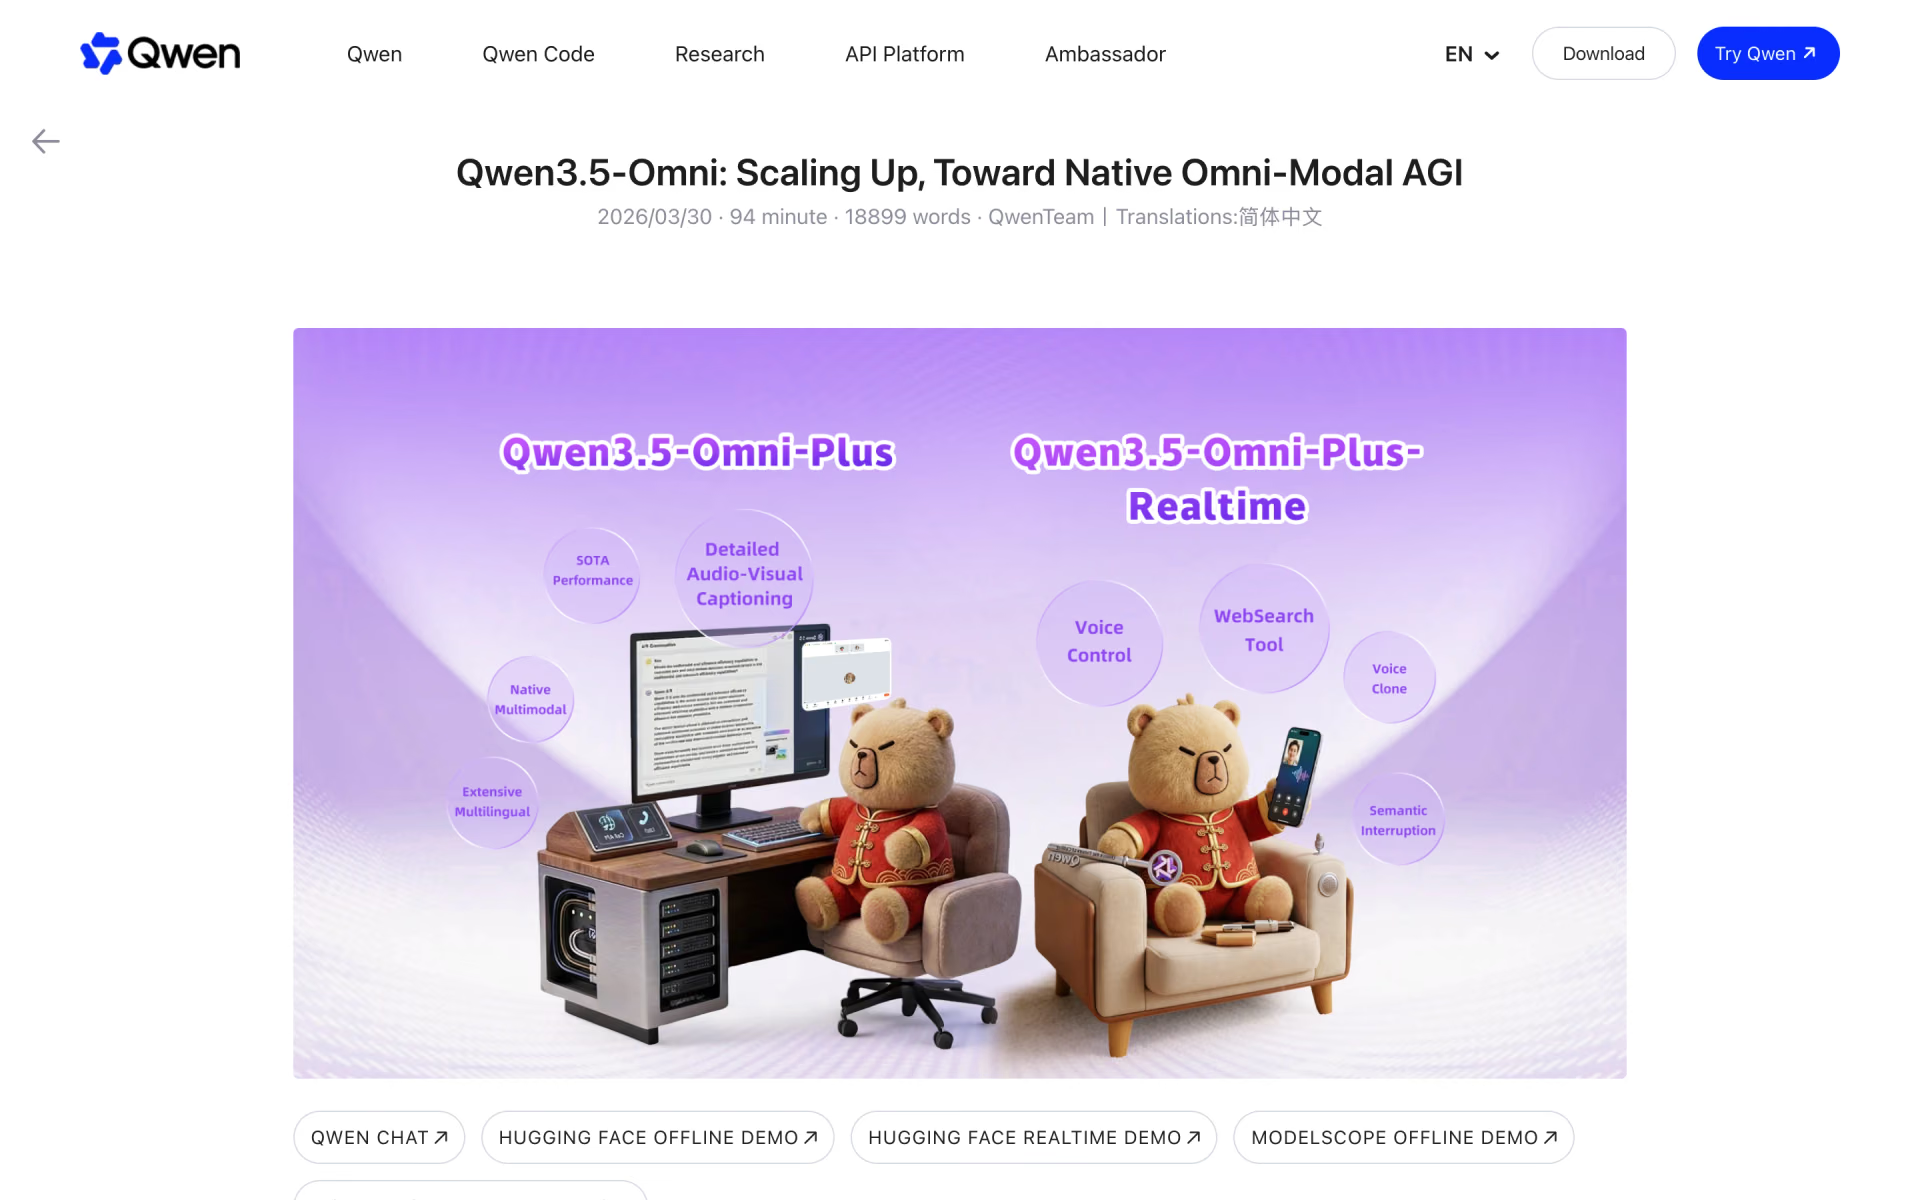
Qwen3.5-Omni is one model that listens, watches and speaks: it reads text, images, audio and video together and replies in text or a spoken voice, instead of chaining separate speech-to-text, language and text-to-speech models. It comes as Plus and Flash on Alibaba Cloud Model Studio, each with a Realtime version for live voice. Qwen has not released the weights; its technical report says the model runs to hundreds of billions of parameters.
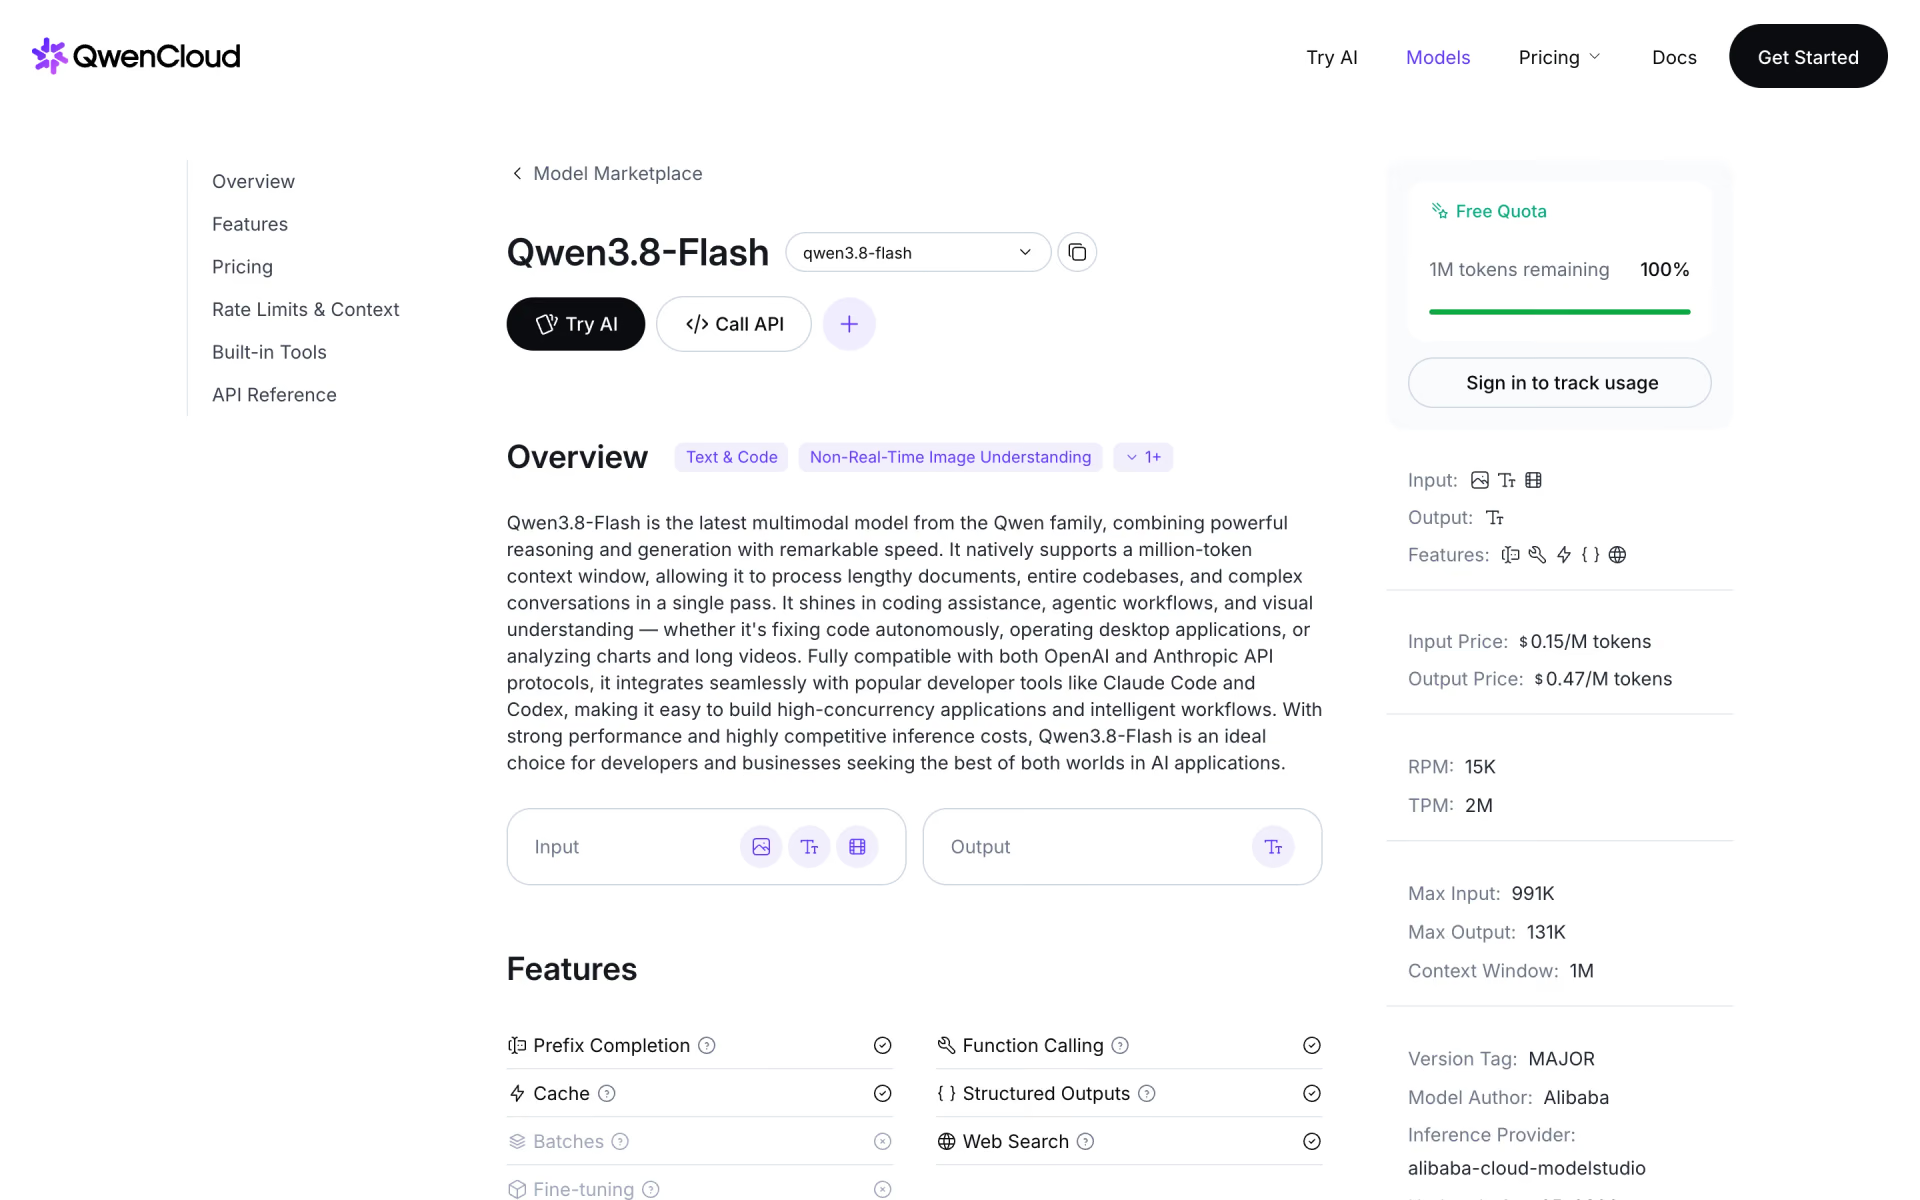
It is still sold, but it is no longer Alibaba's newest omni model. Model Studio now sends text-only analysis to Qwen3.8-Omni-Flash and live voice to Qwen3.8-Omni-Flash-Realtime, and keeps Qwen3.5-Omni as its pick for spoken replies on the standard API.
How does Qwen3.5-Omni compare with Qwen3.8-Omni-Flash?
Qwen3.8-Omni-Flash is newer, cheaper and in more regions, but its standard API answers in text only; Qwen3.5-Omni is the one Alibaba keeps for spoken replies.
- Output
- Qwen3.8-Omni-Flash writes text; its separate Realtime version speaks. Qwen3.5-Omni speaks on both its standard and Realtime APIs.
- Price
- Qwen3.8-Omni-Flash costs $0.15 in and $0.47 out per million tokens in Singapore, against $0.40 and $2.20 for Qwen3.5-Omni-Flash.
- Context
- 1M tokens with up to 131,072 tokens of output, against 256K and 65,536 for Qwen3.5-Omni.
- Regions and thinking
- Qwen3.8-Omni-Flash runs in all six Model Studio regions and can think before answering; Qwen3.5-Omni runs in two and has no thinking mode.
Who is Qwen3.5-Omni best for?
Qwen3.5-Omni is best for developers building voice assistants, transcription or video-understanding apps that need one model to take in text, images, audio and video and reply in text or speech.
Long recordings and video
One API request takes audio files up to 3 hours or video files up to 1 hour, inside a 256K-token context.
Multilingual voice products
It recognises speech in 113 languages and dialects and speaks 36, so one model covers many markets.
Spoken replies from files
Alibaba still names it the model to use when a standard, non-live API call has to answer in a voice.
Detailed captions and transcripts
Plus writes structured, time-stamped descriptions of audio and video that name the speakers and describe the sounds.
What's included with Qwen3.5-Omni?
Spoken answers in 55 voices, voice cloning and voice control, interruption handling for live calls, web search and tool calls, and mixed inputs in one request.
- Speech output
- Answers in text or in one of 55 voices, 47 of them multilingual and 8 in dialects.
- Voice cloning
- Makes a custom voice from 10 to 20 seconds of clear speech, for Plus, Flash and both Realtime models.
- Voice control
- Follows instructions to change its volume, speaking speed and emotion.
- Semantic interruption
- The Realtime versions tell a real interruption apart from a listener's 'mm-hm' or background noise.
- Web search and tool calls
- Every version can search the web; function calls work on the Realtime versions, and on the standard API only in Beijing.
- Mixed inputs in one request
- Any mix of text, images, audio and video in a single call, with files up to 2 GB by URL.
How much does Qwen3.5-Omni cost?
Qwen3.5-Omni is billed per token on Alibaba Cloud Model Studio, from $0.40 per million input tokens and $2.20 per million output tokens for Qwen3.5-Omni-Flash up to $2.10 and $12.40 for Qwen3.5-Omni-Plus-Realtime, with audio in and out priced higher.
- Text, image or video in, text out; audio input $3 per million tokens
- Speech output $11.90 per million tokens, billed on the audio only
- 1M free tokens for 90 days in Singapore
- Text or image in, text out; audio input $4.50 per million tokens
- Speech output $17.70 per million tokens, billed on the audio only
- Live voice sessions through the Realtime API
- Text, image or video in, text out; audio input $11 per million tokens
- Speech output $44 per million tokens, billed on the audio only
- 1M free tokens for 90 days in Singapore
- Text or image in, text out; audio input $16.50 per million tokens
- Speech output $62 per million tokens, billed on the audio only
- Live voice sessions through the Realtime API
These are pay-as-you-go prices for the Singapore (International) region; Model Studio does not offer Qwen3.5-Omni in its US (Virginia) region. In the China (Beijing) region, Plus costs $0.96 in and $5.50 out and Flash $0.30 in and $1.83 out per million tokens for text, image or video in and text out. Each model, Realtime ones included, comes with 1 million free tokens in Singapore, valid for 90 days from Model Studio activation or the model's release, whichever is later. The Light size named in the launch post has no API price. Full pricing on alibabacloud.com. We checked these prices on .
How do readers rate Qwen3.5-Omni?
No one has rated Qwen3.5-Omni yet. Be the first.
Sign in to rate. One rating per account.
Qwen3.5-Omni pros and cons
It leads Gemini 3.1 Pro on most audio tests in Qwen's tables and speaks 36 languages and dialects, but the weights are closed, it runs in only two regions, and newer Qwen3.8 models cost less.
Pros
- Beats Gemini 3.1 Pro on most audio tests in Qwen's own tables, such as 93.1 against 88.9 on VoiceBench and a word error rate of 1.11 against 3.36 on LibriSpeech.
- Covers far more languages than Qwen3-Omni-Flash: speech recognition in 113 languages and dialects and speech output in 36, up from 19 each.
- Voice cloning, voice control, web search and semantic interruption come built in, none of which Qwen3-Omni had.
- Cheap to start: Flash costs $0.40 per million input tokens, and Singapore accounts get 1 million free tokens per model.
Cons
- The weights are closed, unlike Qwen3-Omni's; several Reddit and Hacker News users called that a letdown because they cannot self-host it or keep data in-house.
- Only in Model Studio's Singapore and Beijing regions; the US, Frankfurt, Tokyo and Hong Kong regions offer only the newer Qwen3.8-Omni-Flash.
- Newer Qwen3.8 models cost far less: Qwen3.8-Omni-Flash-Realtime charges $0.93 per million audio input tokens, against $4.50 on Qwen3.5-Omni-Flash-Realtime.
- In the Singapore region the standard API has no function calling, structured output or batch jobs, and Plus and Flash do not support context caching.
What are the best Qwen3.5-Omni alternatives?
Four tools on Recaply do Qwen3.5-Omni's job. Step-Audio-R1 is open source, so you can run it on your own server.
 GPT-Realtime-2Paid
Choose it when you want OpenAI's live voice agent with adjustable reasoning effort; its audio input costs $32 per million tokens, about twice Qwen3.5-Omni-Plus-Realtime's $16.50.
 Gemini 3.8 LiveFree
Choose it when you want a free tier to build on and cheaper live audio: $3 in and $12 out per million audio tokens, against $4.50 and $17.70 on Qwen3.5-Omni-Flash-Realtime.
 Nemotron 3 Nano OmniFree
Choose it when you must run audio and video understanding on your own GPUs; its weights are open, but it answers only in English text.
 Step-Audio-R1Open Source
Choose it when you want an Apache-licensed model that reasons over speech, sounds and music before answering.
Questions about Qwen3.5-Omni
What is Qwen3.5-Omni?
Qwen3.5-Omni is the Qwen team's model that takes in text, images, audio and video and answers in text or speech, sold on Alibaba Cloud Model Studio for voice apps and media analysis.
Who is Qwen3.5-Omni for?
Qwen3.5-Omni is best for developers building voice assistants, transcription or video-understanding apps that need one model to take in text, images, audio and video and reply in text or speech.
Is Qwen3.5-Omni free?
Qwen3.5-Omni has no free plan for regular use, but the Qwen team runs free demos on Hugging Face and ModelScope, and Model Studio accounts in Singapore get 1 million free tokens per model for 90 days. After that, every API call is billed per token.
How much does an hour of audio cost with Qwen3.5-Omni?
Reading an hour of audio costs about 8 cents on Flash and 28 cents on Plus in Singapore, because Alibaba counts 7 tokens per second of input audio. Spoken replies cost more: 12.5 tokens per second, at $11.90 per million on Flash.
Is there an open source alternative to Qwen3.5-Omni?
Yes. Step-Audio-R1 is an open source tool that does the same job, so you can run your own.
What are the best Qwen3.5-Omni alternatives?
The closest alternatives on Recaply are GPT-Realtime-2, Gemini 3.8 Live, Nemotron 3 Nano Omni and Step-Audio-R1.
Can I download Qwen3.5-Omni and run it myself?
No. Qwen has not released weights for Qwen3.5-Omni; it runs only on Alibaba Cloud Model Studio and in the free demos. The newest Qwen omni model with open weights is the older Qwen3-Omni-30B-A3B.
Which Alibaba Cloud regions offer Qwen3.5-Omni?
Alibaba Cloud Model Studio lists Qwen3.5-Omni only in its Singapore and China (Beijing) regions. The Hong Kong, Tokyo, Frankfurt and US (Virginia) regions offer only the newer Qwen3.8-Omni-Flash, so the prices shown here are the Singapore ones.
How long can a Qwen3.5-Omni voice session last?
A Realtime session over WebSocket lasts up to 120 minutes before the connection closes. Within it, Plus keeps up to 100 audio turns or 600 seconds of audio in memory and Flash up to 80 turns or 480 seconds; older history is dropped.
Our verdict
Qwen3.5-Omni is worth testing if you need one model that listens, watches and talks back, and Alibaba's Singapore region works for you.
Qwen's own tests put Plus ahead of Gemini 3.1 Pro on most audio tasks, and Flash is cheap to start, but the weights are closed and the newer Qwen3.8 omni models cost far less for text answers and live voice.
- Skip it for
- Teams that need open weights, a US or European region, or only text answers, where Qwen3.8-Omni-Flash costs a fraction.
- Check first
- Test Qwen3.8-Omni-Flash-Realtime on your own calls before you build a live voice app on Qwen3.5-Omni.
 Qwen3.8-Flash

 Qwen3.6-Plus
 Qwen3.7-Max
 MiMo-V2.6-Flash

 MiMo-V2.6-Pro
 Qwen3.5 Small