
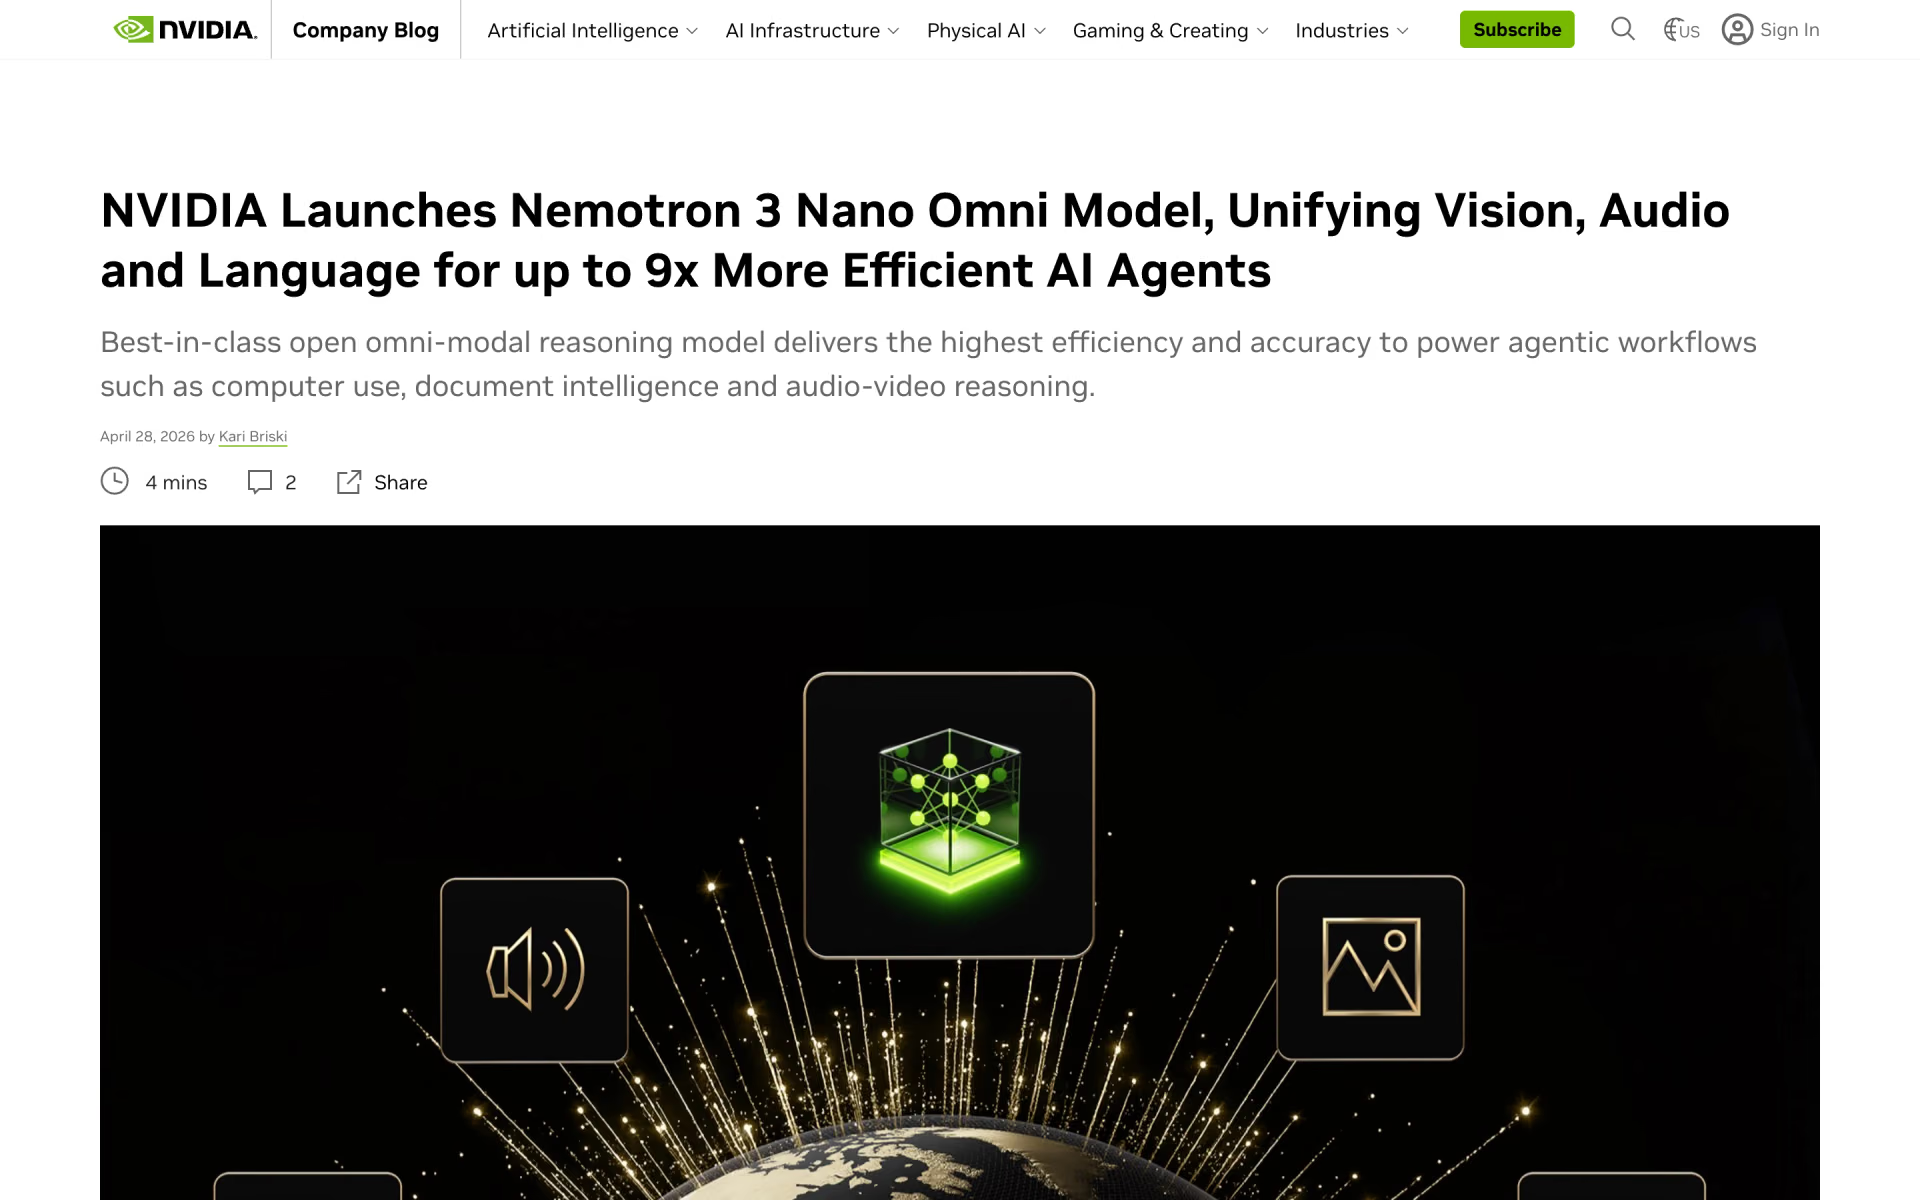
What is Nemotron 3 Nano Omni?
Nemotron 3 Nano Omni is a 30B-A3B mixture-of-experts model from NVIDIA that joins the Nemotron 3 Nano language model to a vision encoder and a Parakeet speech encoder. It reasons by default, which you can switch off per request, and handles screen recordings, meeting audio, charts and scanned pages in one model instead of a chain of separate ones.
NVIDIA pitches it as the eyes and ears of an agent system, working beside a planner such as Nemotron 3 Super or Ultra rather than replacing one. It is NVIDIA's current omni model, and its weights, image training data and training recipes are all public.
Who is Nemotron 3 Nano Omni best for?
Nemotron 3 Nano Omni is best for video and meeting analysis, document intelligence, perception sub-agents inside larger agent systems, and private deployments on your own GPUs.
Video and meeting analysis
It follows speech and on-screen content together, takes audio files up to an hour, and returns word-level timestamps for transcripts.
Document intelligence
NVIDIA reports 67.04 on OCRBenchV2 and 57.5 on MMlongBench-Doc for reading contracts, charts and long scanned documents.
Perception sub-agents
With 3B active parameters it is cheap to run many copies, and NVIDIA measured up to 9.2 times the video-reasoning capacity of other open omni models.
Private deployments
The open weights run on your own GPUs, from one RTX 5090 or a Jetson Thor to data centre servers, so recordings never leave your network.
What's included with Nemotron 3 Nano Omni?
Video, audio, image and text input, switchable reasoning, three precisions down to 21 GB, tool calling and JSON, common inference engines, and open training recipes.
- Omni-modal input
- Video (mp4 up to 2 minutes), audio (wav or mp3 up to 1 hour), images and text in one request, with text out.
- Switchable reasoning
- Reasoning is on by default; turn it off with enable_thinking or cap it with a reasoning budget.
- Three precisions
- BF16 (62 GB), FP8 (33 GB) and NVFP4 (21 GB) checkpoints; NVIDIA says the smaller builds stay within about a point of BF16 on average.
- Tool calling and JSON
- Supports tool calling, JSON output and word-level timestamps for transcription.
- Common inference engines
- Runs in vLLM, SGLang, TensorRT-LLM, llama.cpp and Ollama, or as NVIDIA's NIM container.
- Open training recipes
- NVIDIA published its image training set and the full pre-training, post-training and evaluation recipes, so you can fine-tune it.
How much does Nemotron 3 Nano Omni cost?
Nemotron 3 Nano Omni is free: the weights cost nothing to download and use commercially, NVIDIA's trial endpoint is free, and otherwise you pay for GPUs or a partner's per-token rate, such as $0.10 / $0.25 per million tokens on Vultr.
- Free to use commercially under the NVIDIA Open Model Agreement
- BF16, FP8 and NVFP4 checkpoints on Hugging Face
- You pay only for the GPUs to run it
- For prototyping, under NVIDIA's API trial terms
- Prompts and replies are recorded to improve NVIDIA products
- Needs a free NVIDIA API key
- For running NVIDIA's NIM container in production
- 90-day free evaluation
- Education, Inception and Connect members pay $1,125
NVIDIA sells no per-token plan for Nemotron 3 Nano Omni. Partner hosts set their own prices: NVIDIA's model page lists Vultr at $0.10 per million input tokens and $0.25 per million output tokens, and NVIDIA also links a free listing on OpenRouter. NVIDIA AI Enterprise is also sold as a perpetual licence with five years of support at $22,500 per GPU, or at $1 per GPU per hour plus instance costs on cloud marketplaces, and a five-year subscription comes with H100, H200 NVL and A800 PCIe GPUs. Full pricing on build.nvidia.com. We checked these prices on .
How do readers rate Nemotron 3 Nano Omni?
No one has rated Nemotron 3 Nano Omni yet. Be the first.
Sign in to rate. One rating per account.
Nemotron 3 Nano Omni pros and cons
It is free, open and fast at turning video, audio and documents into text, but users find it weak at reasoning and it works only in English.
Pros
- Free, commercially usable open weights, with the image training data and full training recipes published too.
- One model covers video, audio, images and text, and NVIDIA measured up to 9.2 times the video-reasoning capacity of other open omni models at the same responsiveness.
- Users testing it locally and on video clips call it fast, and the 21 GB NVFP4 build runs on a single RTX 5090.
- NVIDIA says it leads the document, video and audio leaderboards it cites, including OCRBenchV2, MMlongBench-Doc, WorldSense, DailyOmni and VoiceBench.
Cons
- Weak as a general reasoner: several Reddit users who ran it beside Gemma 4 and Qwen3.6 rated it the least capable, and one got broken HTML twice in a row.
- English only, with video capped at 2 minutes per file and no speech output.
- Audio takes extra setup: early users could not send audio through llama.cpp's server or Open WebUI, and NVIDIA's DGX Spark recipes install audio packages separately.
- Running NVIDIA's NIM container in production needs NVIDIA AI Enterprise at $4,500 per GPU per year, and the free trial endpoint records what you send.
What are the best Nemotron 3 Nano Omni alternatives?
Three tools on Recaply do Nemotron 3 Nano Omni's job. Gemma 4 is open source, so you can run it on your own server.
 Gemma 4Open Source
Choose it when you want an Apache 2.0 licence or a model small enough for a phone; its E2B and E4B sizes take audio too, but only 30-second clips against Nano Omni's one hour.
 Qwen3.5-OmniFreemium
Choose it when you need spoken replies or languages beyond English: it recognises speech in 113 languages and talks in 36, but it is API-only, from $0.40 per million input tokens ($3 for audio).
 Gemini 3.8 FlashFree
Choose it when you would rather not run GPUs: Google hosts it with a free tier, a 1M-token context and the same video, audio and image inputs, at $1.50 / $7.50 per million tokens on the normal paid tier.
Questions about Nemotron 3 Nano Omni
What is Nemotron 3 Nano Omni?
Nemotron 3 Nano Omni is NVIDIA's free, open-weight model that reads video, audio, images and text in one pass and answers in text, built to be the perception sub-agent in larger agent systems.
Who is Nemotron 3 Nano Omni for?
Nemotron 3 Nano Omni is best for video and meeting analysis, document intelligence, perception sub-agents inside larger agent systems, and private deployments on your own GPUs.
Is the free build.nvidia.com endpoint private?
No. NVIDIA's trial terms say inputs and outputs on the free endpoint are recorded to improve its products, so keep confidential data off it and run the weights yourself or through a partner host for private work.
How much does Nemotron 3 Nano Omni cost?
Nemotron 3 Nano Omni's paid plans are NVIDIA AI Enterprise at $4,500 per GPU per year.
Is there an open source alternative to Nemotron 3 Nano Omni?
Yes. Gemma 4 is an open source tool that does the same job, so you can run your own.
What are the best Nemotron 3 Nano Omni alternatives?
The closest alternatives on Recaply are Gemma 4, Qwen3.5-Omni and Gemini 3.8 Flash.
Where can I try Nemotron 3 Nano Omni?
On its official website, blogs.nvidia.com.
Can I run Nemotron 3 Nano Omni on my own GPU?
Yes. NVIDIA lists one H100 80GB as the minimum for the BF16 weights, one L40S 48GB for FP8, and one RTX 5090 32GB for the 21 GB NVFP4 build, which also runs on DGX Spark and Jetson Thor. It works with vLLM, SGLang, TensorRT-LLM, llama.cpp and Ollama.
Can I use Nemotron 3 Nano Omni commercially?
Yes. It is released under the NVIDIA Open Model Agreement, which allows commercial use and derivative models, and NVIDIA claims no ownership of what the model outputs. If you redistribute the weights, you must pass on the licence and keep NVIDIA's notices.
Does Nemotron 3 Nano Omni generate speech?
No. Nemotron 3 Nano Omni takes video, audio, images and text but answers only in text, and it works in English only. For spoken replies you need a separate text-to-speech model or an omni model with speech output, such as Qwen3.5-Omni.
Can Nemotron 3 Nano Omni read PDFs?
Not as raw files. NVIDIA's model card says the API does not accept PDF uploads, so you render each page to a PNG image and send the images; the model then reads the text, tables and charts on those pages.
Our verdict
Nemotron 3 Nano Omni is a good free pick for turning video, audio and documents into text inside an agent system, but not as the agent's main brain.
It is open, commercially usable and runs on one GPU, and NVIDIA's tests show strong document and video scores at far higher throughput than other open omni models, while users find its general reasoning weak.
- Skip it for
- Work outside English, anything that needs spoken replies, and tasks where the model must plan and reason on its own.
- Check first
- Test it on your own recordings and documents first, and budget for NVIDIA AI Enterprise if you plan to run the NIM container in production.

 NVIDIA Nemotron 3 Ultra

 Nemotron 3
 Nemotron 3 Super
 GPT-5.4 mini & nano
 Nemotron 3.5 Lightning

 LFM3