

What is Gemini 3.5 Flash-Lite?
Gemini 3.5 Flash-Lite is the Flash-Lite model of Google's Gemini 3.5 line, built on 3.1 Flash-Lite for high-volume, low-latency work. It reads text, images, video, audio and PDFs across a 1M-token context and writes text. Thinking defaults to minimal for speed, and Google says to raise it to medium or high when the model runs as a subagent that writes code or calls tools. Its knowledge stops at March 2026.
It is current and stable, and Google recommends it or 3.8 Flash for new projects; it also replaces 3.1 Flash-Lite, which has a shutdown date. The catch is price: $0.30 / $2.50 per million tokens, up from $0.25 / $1.50.
What changed from Gemini 3.1 Flash-Lite?
Much better at agent and coding work, but more expensive, with a few API behaviour changes.
- Price
- $0.30 / $2.50 per million tokens against $0.25 / $1.50, though audio input no longer costs double.
- Scores
- Terminal-Bench 2.1 rose from 31.0% to 54.0% and OSWorld-Verified from 54.3% to 74.0% in Google's tests.
- Parameters
- Custom temperature, top-P and top-K are ignored, and penalty settings return an error.
- Status
- 3.1 Flash-Lite now has a shutdown date, with 3.5 Flash-Lite as its named replacement.
Who is Gemini 3.5 Flash-Lite best for?
Gemini 3.5 Flash-Lite is best for subagents under a larger model, classification and extraction, documents and media at volume, and bulk jobs on Batch or Flex.
Subagents under a larger model
At medium or high thinking it handles multi-step tool use; Google's table puts it at 74.0% on OSWorld-Verified computer use, ahead of GPT-5.4 mini's 72.1%.
Classification, routing and extraction
Minimal thinking by default keeps answers quick and cheap, and structured output returns JSON in the shape you define.
Documents, images and media at volume
Audio input costs the same $0.30 per million tokens as text, where 3.1 Flash-Lite charged double for audio.
Bulk jobs that can wait
Batch and Flex halve the price to $0.15 in and $1.25 out per million tokens.
What's included with Gemini 3.5 Flash-Lite?
Four thinking levels, built-in tools with Search grounding, computer use in preview, agentic video understanding, context caching, Batch, Flex and Priority tiers, and enterprise controls on Google Cloud.
- Thinking levels
- Minimal, low, medium and high trade depth against speed and cost; minimal is the default.
- Built-in tools
- Function calling, code execution, Google Search and Maps grounding, URL context, file search and structured output.
- Computer use (preview)
- It can operate a computer screen through Google's computer use tool, which is still in preview.
- Agentic video understanding
- For long videos it fetches transcripts, frames or audio only as needed, which Google says uses up to 88% fewer tokens.
- Context caching
- Cached input costs $0.03 per million tokens, plus $1.00 per million tokens per hour of storage.
- Batch, Flex and Priority
- Batch and Flex halve the price, and Priority costs 1.8 times the Standard rate.
- Enterprise controls
- On Gemini Enterprise Agent Platform it runs in US or EU multi-regions with data residency, customer-managed keys and VPC Service Controls.
How much does Gemini 3.5 Flash-Lite cost?
Gemini 3.5 Flash-Lite is free on the Gemini API's rate-limited free tier, and paid use costs $0.30 per million input tokens and $2.50 per million output tokens, or half that on Batch or Flex.
- Free input and output tokens at lower rate limits
- Prompts and responses are used to improve Google's products
- No context caching or Search grounding
- Half the Standard rate
- Cached input $0.02
- Same input price for text, images, video and audio; output includes thinking tokens
- Cached input $0.03, plus $1.00 per million tokens per hour of storage
- 5,000 Google Search grounding requests a month free, then $14 per 1,000
- 1.8 times the Standard rate
- Cached input $0.05
Prices are for the Gemini Developer API in US dollars. Paid use needs a linked billing account and at least $5 of prepaid credit, which expires after 12 months, and paid-tier prompts are not used to improve Google's products. The free Search grounding allowance is shared across Gemini 3 models, and Google Maps grounding also gives 5,000 free requests a month, then $14 per 1,000. Google AI Studio is free to use, and prices on Gemini Enterprise Agent Platform can differ. Full pricing on ai.google.dev. We checked these prices on .
How do readers rate Gemini 3.5 Flash-Lite?
No one has rated Gemini 3.5 Flash-Lite yet. Be the first.
Sign in to rate. One rating per account.
Gemini 3.5 Flash-Lite pros and cons
It is fast and a clear step up from 3.1 Flash-Lite, but it costs more than earlier Flash-Lite models and can stumble in agent loops at its default settings.
Pros
- Users on Hacker News and Reddit call it very fast, fast enough for rapid iteration; Google cites 350 output tokens per second, as measured by Artificial Analysis.
- A clear step up from 3.1 Flash-Lite that users noticed: in Google's tests it scores 54.0% against 31.0% on Terminal-Bench 2.1 and 1140 against 642 on GDPval-AA v2.
- Cheap enough to iterate on: Reddit users generating app interfaces found its output close to 3.6 Flash's at a fraction of the cost.
- One input price for every kind of media, and a free API tier with no end date for testing.
Cons
- Each Flash-Lite generation has cost more, a common Hacker News complaint: $0.30 / $2.50 per million tokens against $0.25 / $1.50 for 3.1 Flash-Lite and $0.10 / $0.40 for 2.5 Flash-Lite.
- Several Hacker News users say cheaper open models, DeepSeek's Flash line in particular, match or beat it for less money.
- Some developers found it unreliable in agent loops, with missed instructions and wrong tool calls; Google itself warns that the default minimal thinking can end multi-step tool use early.
- Older code may need changes: custom temperature, top-P and top-K values are ignored, penalty settings return an error, and requests that end on a model turn fail.
What are the best Gemini 3.5 Flash-Lite alternatives?
Five tools on Recaply do Gemini 3.5 Flash-Lite's job. DeepSeek V4.1 Flash, 1-bit Bonsai and Mellum2 are open source, so you can run them on your own server.
 Gemini 3.8 FlashFree
Choose it when subagents need stronger reasoning or long coding runs; it is Google's most capable Flash model, with the same 1M context and free tier, at $1.50 / $7.50 per million tokens.
 DeepSeek V4.1 FlashOpen Source
Choose it when output cost matters most; it charges $0.30 / $1.20 per million tokens at peak and half that off-peak, with a 1M context, though it reads text and images only.
 GPT-5.4 mini & nanoPaid
Choose it when you build on OpenAI; nano costs $0.20 / $1.25 per million tokens and mini $0.75 / $4.50, both with a 400K context but no audio or video input.
 1-bit BonsaiOpen Source
Choose it when high-volume text tasks must stay on the device, with no per-token bill and nothing sent to Google.
 Mellum2Open Source
Choose it when you want a 12B open model for routing, RAG and sub-agent steps that runs on your own servers.
More open source alternatives
See all
Questions about Gemini 3.5 Flash-Lite
What is Gemini 3.5 Flash-Lite's knowledge cutoff?
March 2026, though Google says some domains only reach January 2025, as with the rest of the Gemini 3 family. Search grounding can fill the gaps: 5,000 grounded requests a month are free on the paid tier, then $14 per 1,000.
Who is Gemini 3.5 Flash-Lite for?
Gemini 3.5 Flash-Lite is best for subagents under a larger model, classification and extraction, documents and media at volume, and bulk jobs on Batch or Flex.
Is Gemini 3.5 Flash-Lite free?
Yes. Gemini 3.5 Flash-Lite has a free Free tier plan: free input and output tokens at lower rate limits.
How much does Gemini 3.5 Flash-Lite cost?
Gemini 3.5 Flash-Lite's paid plans are Batch or Flex at $0.15 / $1.25 per million input / output tokens, Standard at $0.30 / $2.50 per million input / output tokens and Priority at $0.54 / $4.50 per million input / output tokens.
Is there an open source alternative to Gemini 3.5 Flash-Lite?
Yes. DeepSeek V4.1 Flash, 1-bit Bonsai, Mellum2 and Nemotron 3.5 Lightning are open source tools that do the same job, so you can run your own.
What are the best Gemini 3.5 Flash-Lite alternatives?
The closest alternatives on Recaply are Gemini 3.8 Flash, DeepSeek V4.1 Flash, GPT-5.4 mini & nano, 1-bit Bonsai and Mellum2.
Where can I try Gemini 3.5 Flash-Lite?
On its official website, ai.google.dev.
Which thinking level should I use with Gemini 3.5 Flash-Lite?
Leave it on minimal, the default, for classification, routing and extraction. Google recommends medium or high when it works as a subagent that writes code, runs terminal commands or calls APIs, because minimal can stop multi-step tool use too early.
Gemini 3.5 Flash-Lite vs Gemini 3.8 Flash: which should I use?
Use Flash-Lite for high-volume, latency-sensitive work at $0.30 / $2.50 per million tokens, and 3.8 Flash, Google's most capable Flash model, for long coding and agent jobs at $1.50 / $7.50. Both have a 1M context and a free tier, and Google recommends one of the two for new projects.
Can Gemini 3.5 Flash-Lite replace Gemini 2.5 Flash?
For many workloads, yes: Google names it a suitable replacement for Gemini 2.5 Flash and for simpler Gemini 3 Flash jobs. It matches 2.5 Flash's $0.30 / $2.50 text price, and Google now limits the 2.5 models to projects that already used them.
Does Google train on my Gemini 3.5 Flash-Lite prompts?
On the free tier, Google says prompts and responses are used to improve its products. On the paid tier they are not, so use a paid key for customer data or anything confidential.
Our verdict
Gemini 3.5 Flash-Lite is the Gemini model to use for fast, high-volume work, as long as you test it on your own agent loops.
It clearly beats the 3.1 Flash-Lite it replaces on Google's agent and coding tests, but each Flash-Lite generation has cost more, and DeepSeek V4.1 Flash charges less for output.
- Skip it for
- Long coding or reasoning-heavy agent work, where Gemini 3.8 Flash does better, and pure cost-cutting, where DeepSeek V4.1 Flash or GPT-5.4 nano cost less.
- Check first
- If it runs as a subagent, raise thinking to medium or high before you judge it.

 Gemini 3.1 Flash-Lite
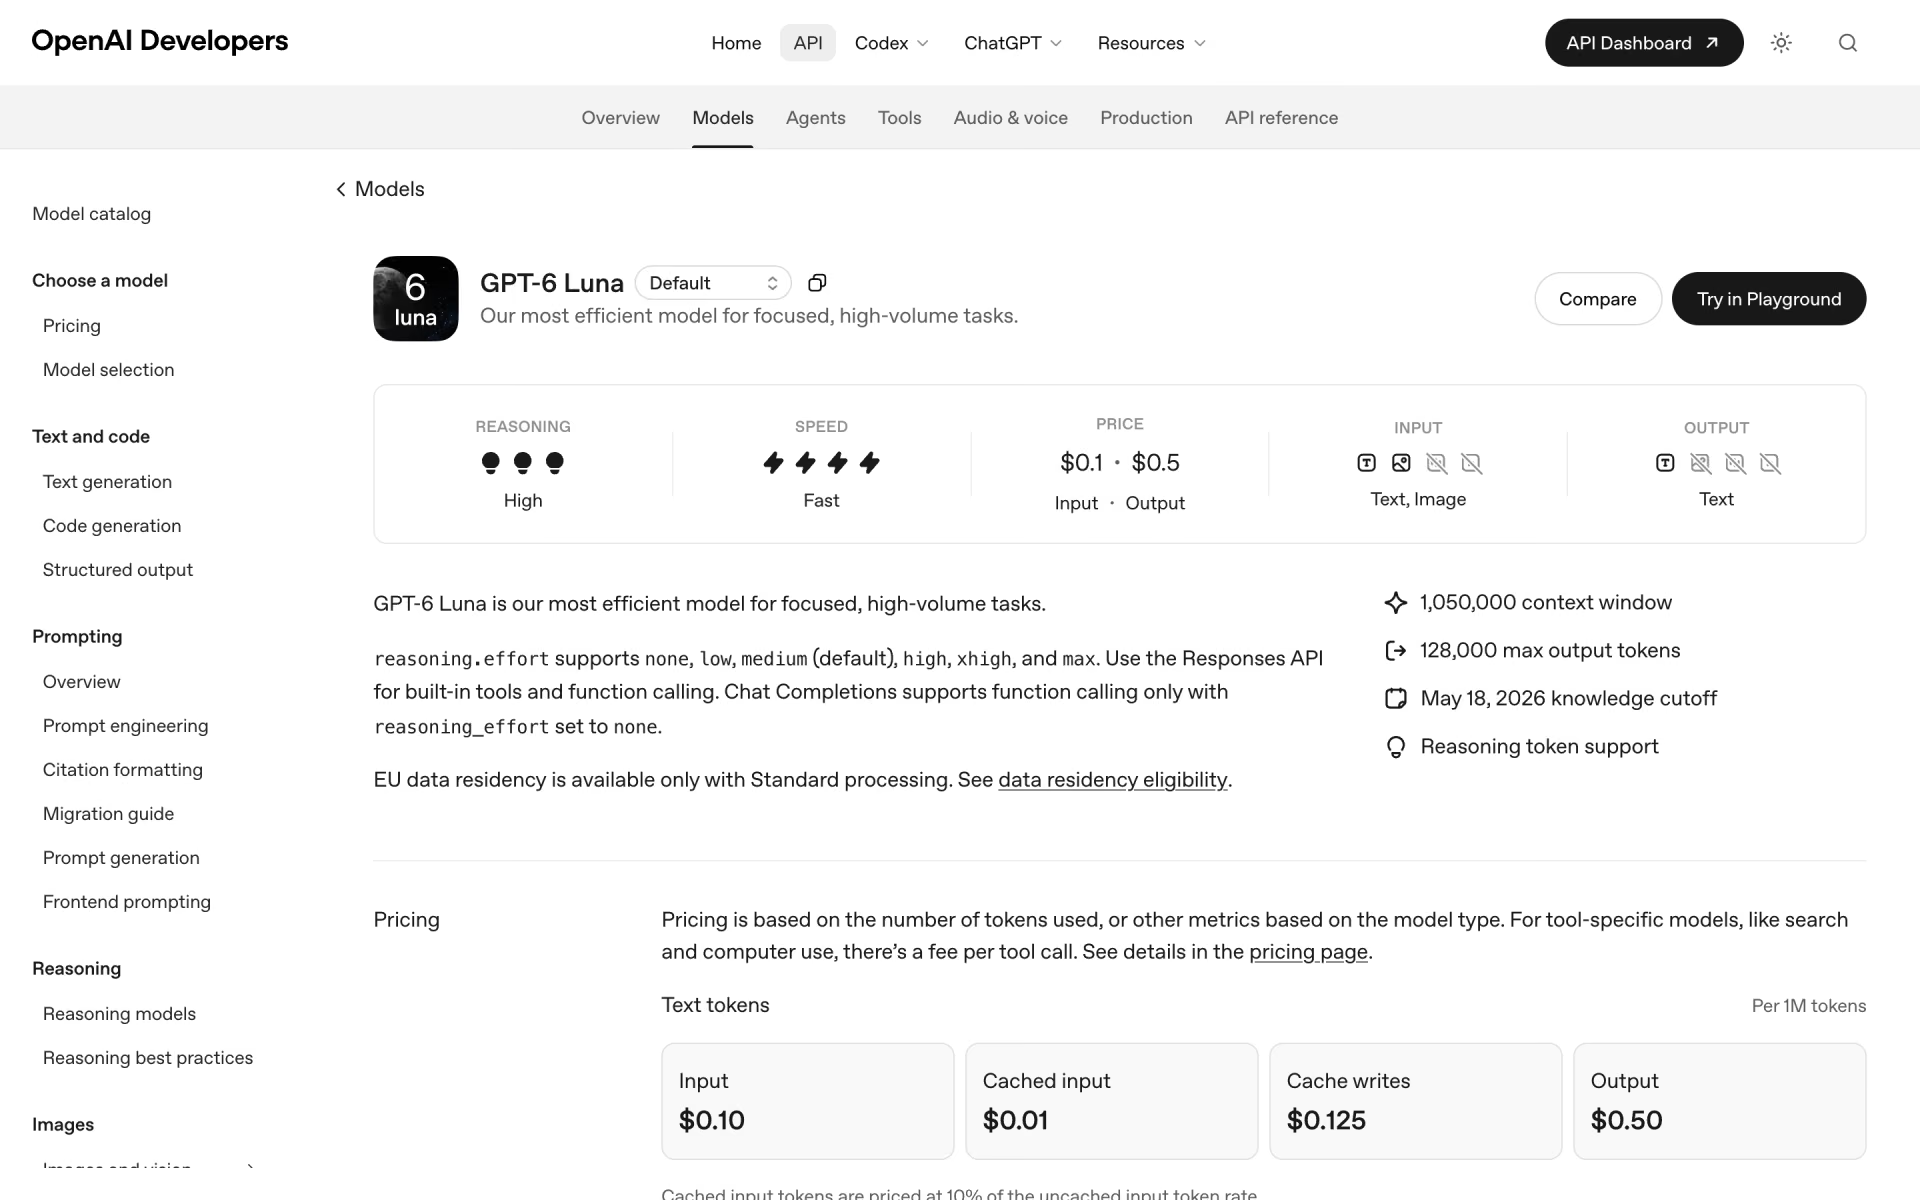
 GPT-6 Luna
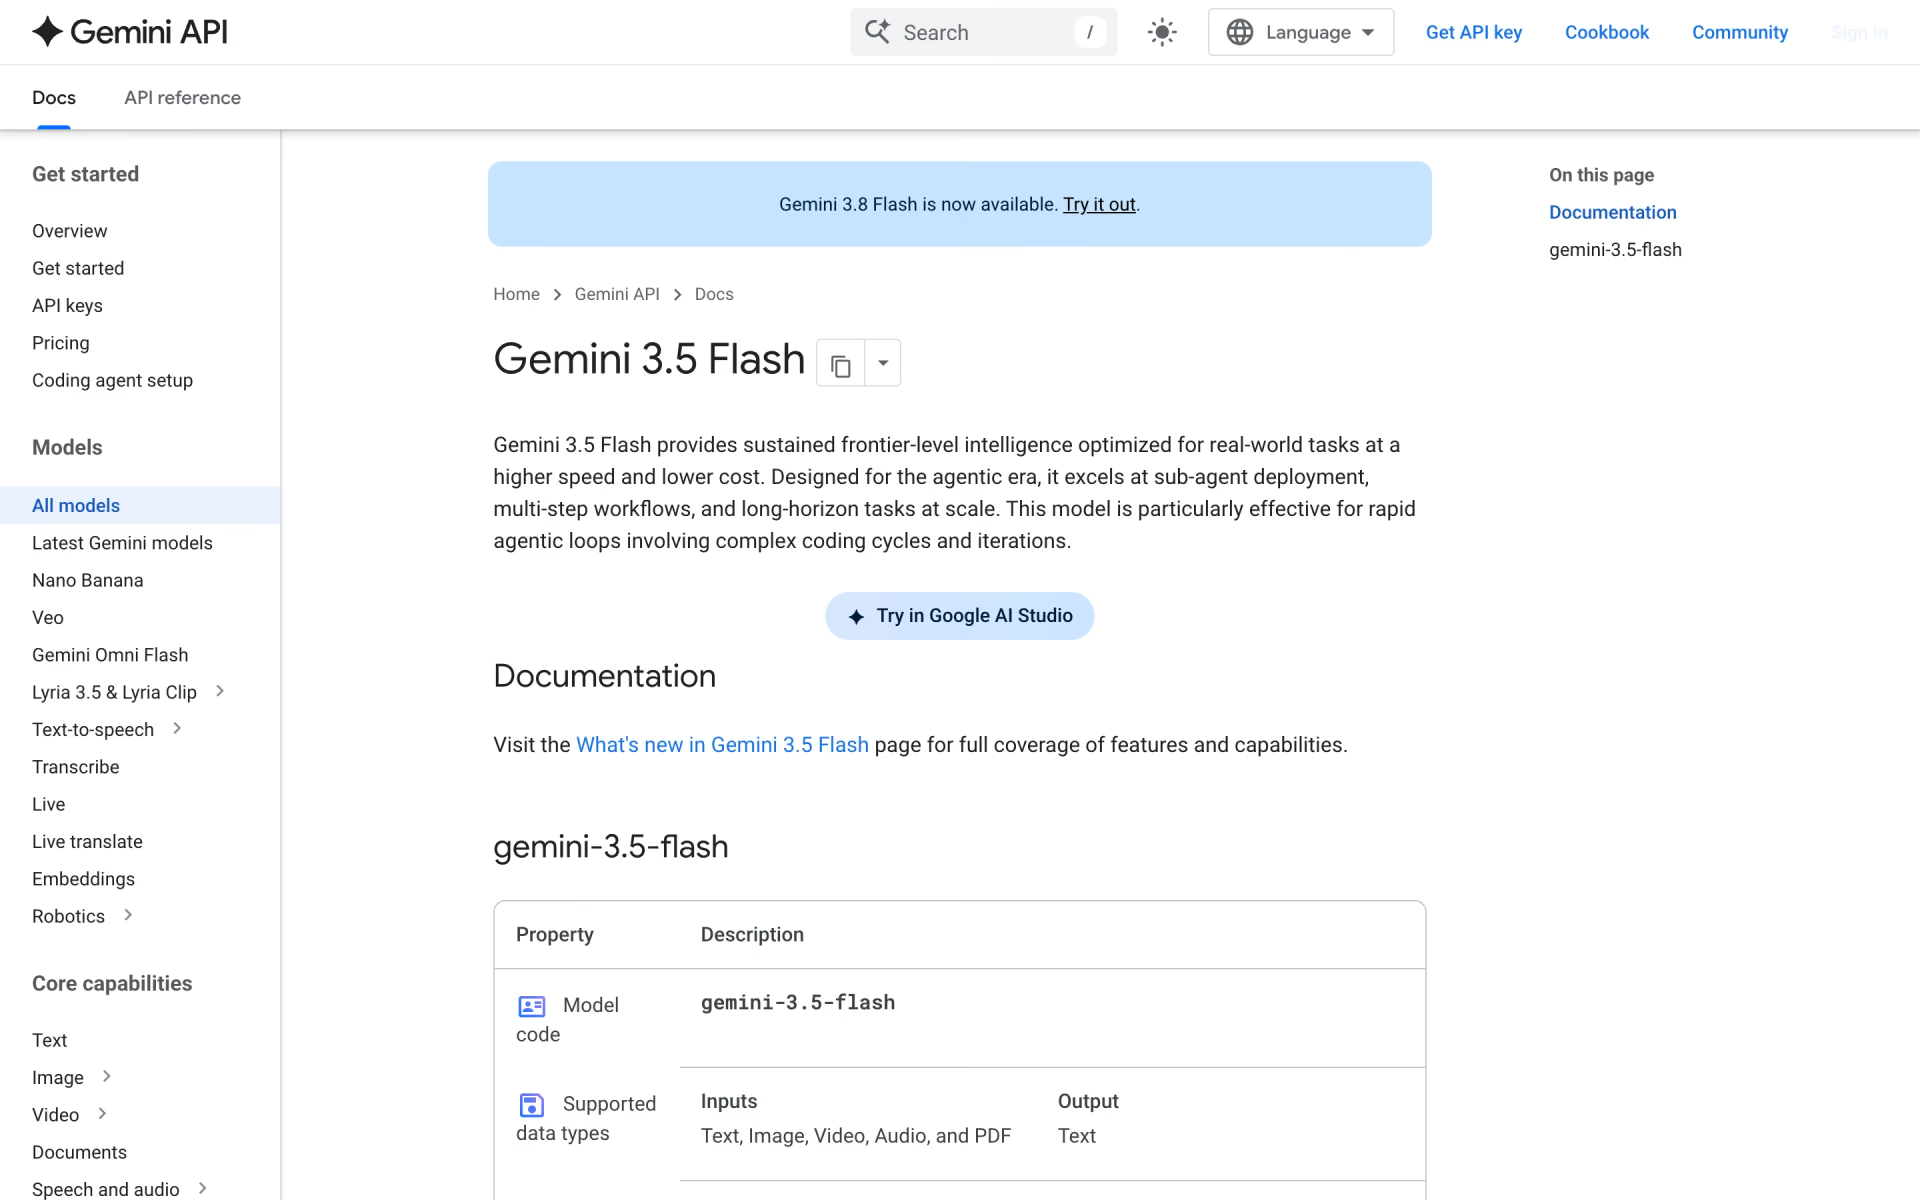
 Gemini 3.5 Flash
 Gemini 3.7 Flash
 Qwen3.8-Flash

 Ultramarine 1 Flash