
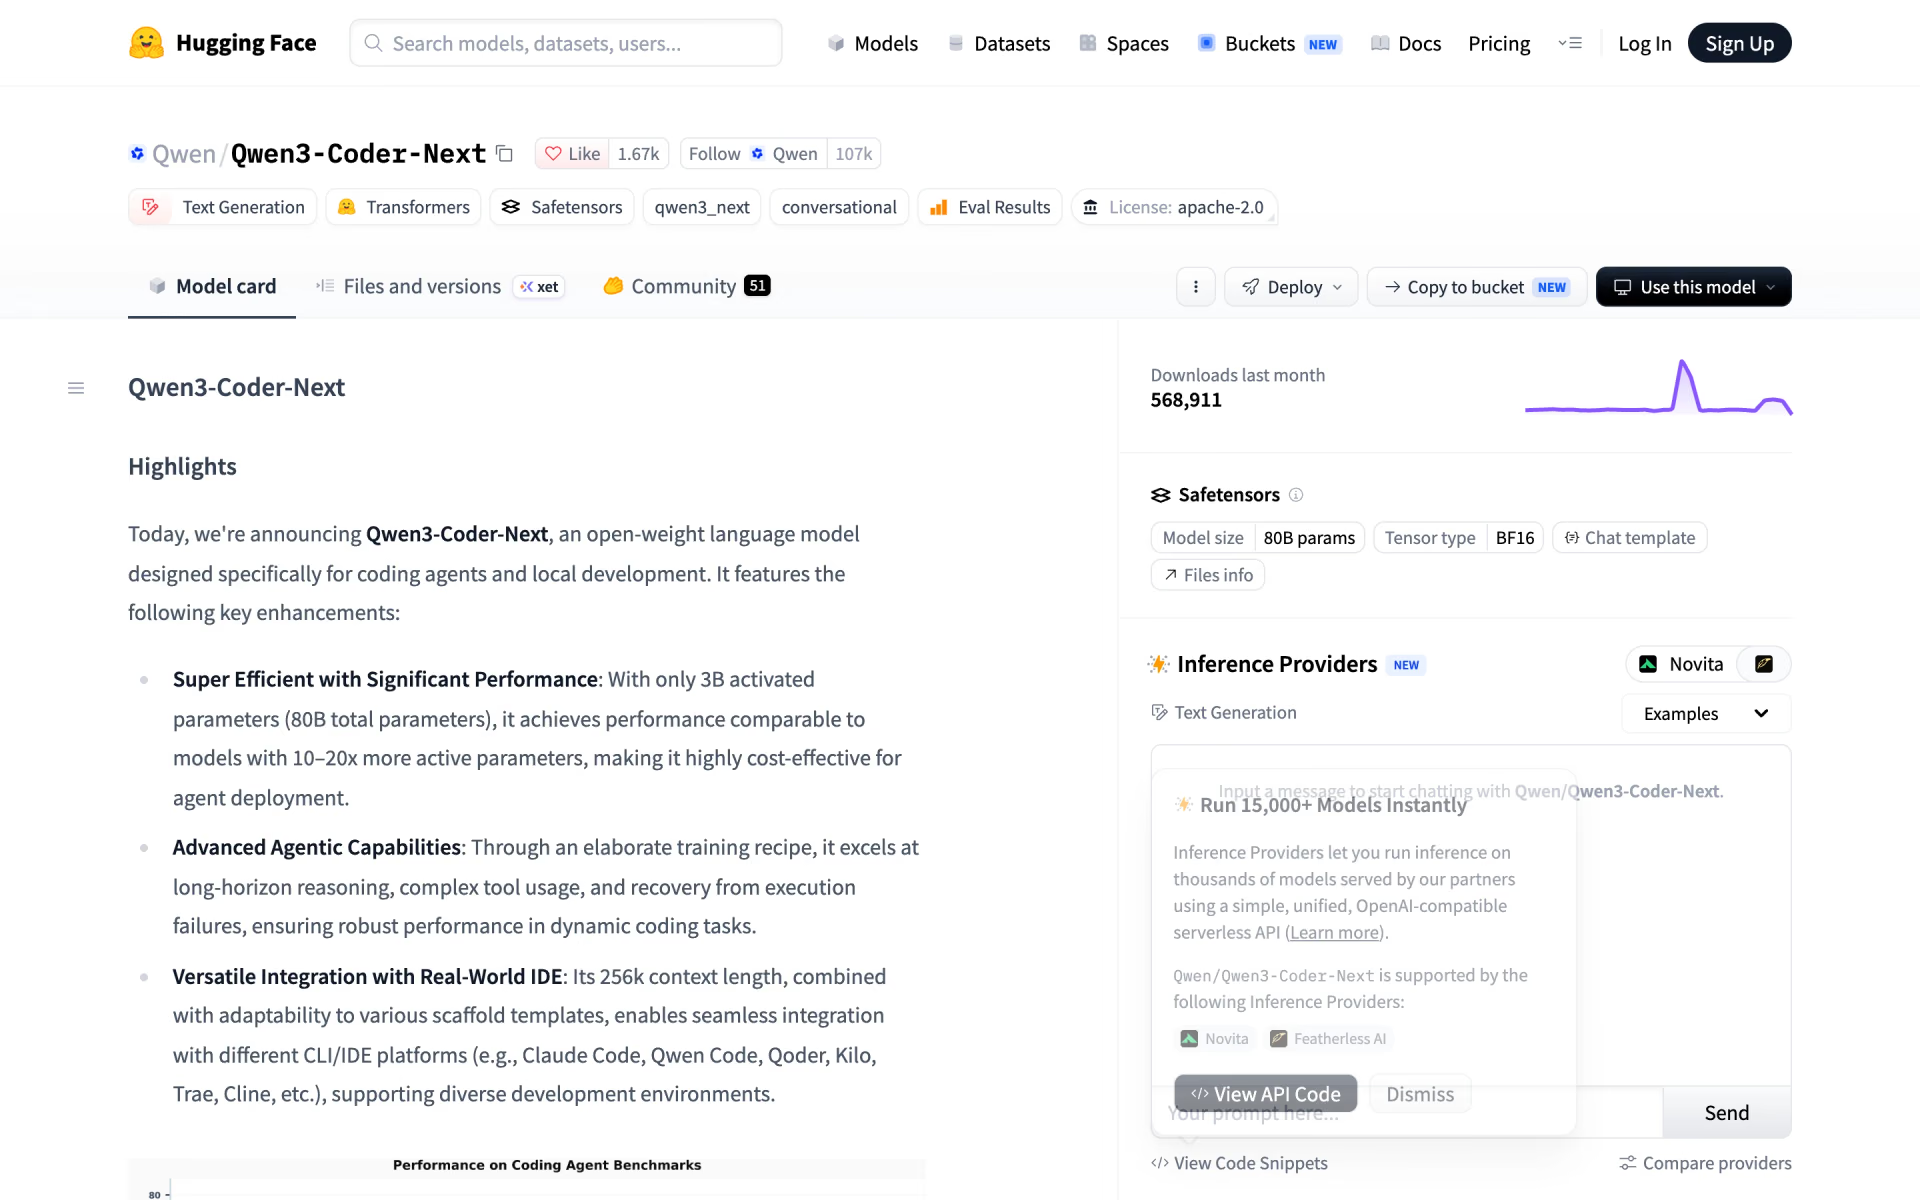
What is Qwen3-Coder-Next?
Qwen3-Coder-Next is a coding model from Alibaba's Qwen team, built on its Qwen3-Next-80B-A3B base and trained with reinforcement learning on large sets of runnable coding tasks. It answers directly with no thinking step, reads and writes text only, and plugs into agents such as Claude Code, Qwen Code, Cline and Kilo. Only 3B of its 80B parameters work on each token, so it generates quickly for its size.
The weights stay free under Apache 2.0, but Qwen Cloud, Qwen's official API service, has scheduled the hosted model for retirement and points API users to Qwen3.7-Plus.
Is Qwen3-Coder-Next still available?
The weights are, but the hosted API is going: Qwen Cloud lists qwen3-coder-next as a legacy model scheduled for retirement.
- Open weights
- Still free on Hugging Face under Apache 2.0, with Qwen's own FP8 and GGUF builds.
- Hosted API
- Once the model retires, calls to qwen3-coder-next on Qwen Cloud fail.
- Named replacement
- Alibaba points API users to Qwen3.7-Plus, at $0.40 / $1.60 per million tokens for inputs up to 256K.
- Before the switch
- Alibaba says rate limits on a retiring model shrink step by step, so test the replacement early.
Who is Qwen3-Coder-Next best for?
Qwen3-Coder-Next is best for developers who want a fast, free coding model on their own hardware and who steer it step by step inside tools like Claude Code, Qwen Code or Cline.
Fast local coding
Only 3B of its 80B parameters work on each token, so it answers quickly on any machine that can hold the weights.
Coding along with a developer
It suits developers who plan the change themselves and hand it clear, step-by-step edits, rather than a loose spec to run with.
Existing agent tools
Its 256K-token context and tool calling fit CLI and IDE agents such as Claude Code, Qwen Code, Cline, Kilo and Trae.
Private, offline coding
The Apache 2.0 weights run on your own hardware, so your code never has to leave your network.
What's included with Qwen3-Coder-Next?
A 3B-active mixture of experts, a 256K context, training for tool use, official FP8 and GGUF builds, and support in the common local runners.
- Mixture of experts
- 512 experts with 10 routed and 1 shared active per token, which adds up to 3B active parameters.
- 256K context
- It reads 262,144 tokens natively; Qwen suggests dropping to 32,768 if your server runs out of memory.
- Trained for tool use
- Qwen trained it on agent runs in executable environments for multi-step tool calls and recovery from failed runs.
- Official quantised builds
- Qwen publishes FP8 and GGUF versions, from a 48 GB 4-bit file up to full precision.
- Common local runners
- SGLang and vLLM serve it as an OpenAI-compatible endpoint, and Ollama, LM Studio, MLX-LM, llama.cpp and KTransformers run it locally.
- No thinking step
- It never writes thinking blocks, so there is no reasoning output to wait for, pay for or parse.
How much does Qwen3-Coder-Next cost?
Qwen3-Coder-Next is free to download and run under the Apache 2.0 licence; Alibaba's hosted API costs from $0.30 per million input tokens and $1.50 per million output tokens, but that hosted model is being retired.
- Apache 2.0 licence on Hugging Face
- 80B parameters with 3B active; 48 GB as a 4-bit GGUF, 159 GB in BF16
- Runs on vLLM, SGLang, Ollama, LM Studio or llama.cpp
- For requests with up to 32K input tokens
- 32K to 128K input: $0.50 / $2.50; 128K to 256K: $0.80 / $4
- Alibaba is retiring this hosted model
API prices are for Alibaba Cloud Model Studio's international deployment in Singapore, and Qwen Cloud lists the same $0.30 / $1.50 starting price; the US (Virginia) region does not offer this model. The EU deployment in Frankfurt charges the same, and the China (Beijing) region charges $0.144 / $0.574 per million tokens for requests up to 32K. Each request is billed at the tier its input size falls in. New Model Studio accounts in Singapore get 1 million free tokens for it, valid for 90 days. Qwen Cloud has scheduled the hosted model for retirement and names Qwen3.7-Plus, at $0.40 / $1.60 per million tokens for inputs up to 256K, as the replacement. Full pricing on alibabacloud.com. We checked these prices on .
How do readers rate Qwen3-Coder-Next?
No one has rated Qwen3-Coder-Next yet. Be the first.
Sign in to rate. One rating per account.
Qwen3-Coder-Next pros and cons
It is quick and dependable when you steer it, but newer Qwen models plan better, it needs about 48 GB even at 4 bits, and its hosted API is retiring.
Pros
- Fast for its quality: users report 35 to 60 tokens a second on a single high-end GPU or an AMD Strix Halo mini PC, because only 3B parameters work per token.
- Developers who steer it step by step call it a dependable implementer inside Claude Code, Zed, Cline or OpenCode.
- It still runs at a usable speed on a 24 GB graphics card when the expert weights spill into system RAM.
- Qwen's chart puts it level with far larger open models, at 70.6% on SWE-Bench Verified against 70.2% for DeepSeek-V3.2.
Cons
- Newer Qwen models beat it for many users: people who compared them found Qwen3.6-27B and even Qwen3.6-35B-A3B better at agentic tasks and planning.
- Early testers say it falls short of the Claude Sonnet level Qwen's charts suggest, and some saw it get stuck in loops, including in Codex CLI.
- It needs about 48 GB even as a 4-bit build, so most laptops cannot run it, and it takes text only, with no image input or thinking mode.
- Qwen Cloud is retiring the hosted model, so API users have to move to Qwen3.7-Plus or host the weights themselves.
Is Qwen3-Coder-Next open source?
Yes. Qwen3-Coder-Next's code is public under the Apache 2.0 licence, so you can run it on your own server.
What are the best Qwen3-Coder-Next alternatives?
Qwen3-Coder-Next is an open source alternative to Kimi K2.7 Code, MiniMax M2.1 and Kimi K2. GLM-4.7 and DeepSeek V4.1 Flash do the same job and are open source too.
 Kimi K2.7 CodeFree
Moonshot's open agentic coding model with a 256K context.
 MiniMax M2.1Free
MiniMax's open-weight coding model tuned for Rust, Java, Go, C++, Kotlin and mobile app work.
 Kimi K2Free
Moonshot's downloadable 1T-parameter MoE for coding and agents.
 GLM-4.7Open Source
Z.ai's MIT-licensed model for agentic coding with a 200K context.
 DeepSeek V4.1 FlashOpen Source
DeepSeek's small, efficient open model.
 Qwen3.6-27BOpen Source
Choose it when you want a newer Qwen coder that also reads images and whose hosted API is not being retired; its FP8 build is about 31 GB against 80 GB for Coder-Next's, though as a dense model it runs slower per token.
Questions about Qwen3-Coder-Next
What is Qwen3-Coder-Next?
Qwen3-Coder-Next is Alibaba's free, open-weight coding model for agents and local work: an 80B mixture of experts that runs only 3B parameters per token, with a 256K-token context.
Who is Qwen3-Coder-Next for?
Qwen3-Coder-Next is best for developers who want a fast, free coding model on their own hardware and who steer it step by step inside tools like Claude Code, Qwen Code or Cline.
Is Qwen3-Coder-Next free?
Yes. Qwen3-Coder-Next's weights are free to download and run under the Apache 2.0 licence; you pay only for your own hardware. Alibaba's hosted API charges from $0.30 per million input tokens, but Qwen Cloud has scheduled that hosted model for retirement.
How much does Qwen3-Coder-Next cost?
Qwen3-Coder-Next's paid plans are Model Studio API at $0.30 / $1.50 per million input / output tokens.
Is Qwen3-Coder-Next open source?
Yes. Qwen3-Coder-Next's code is public under the Apache 2.0 licence, so you can run it on your own server.
What are the best Qwen3-Coder-Next alternatives?
The closest alternatives on Recaply are Kimi K2.7 Code, MiniMax M2.1, Kimi K2, GLM-4.7, DeepSeek V4.1 Flash and Qwen3.6-27B.
Where can I try Qwen3-Coder-Next?
On its official website, huggingface.co.
Can I run Qwen3-Coder-Next locally?
Yes. Qwen3-Coder-Next's full weights take about 159 GB in BF16 and Qwen's own 4-bit GGUF about 48 GB. Qwen documents vLLM and SGLang for serving and Ollama, LM Studio, MLX-LM or llama.cpp for local use, and suggests cutting the context to 32,768 tokens if memory runs short.
Does Qwen3-Coder-Next have a thinking mode?
No. Qwen3-Coder-Next runs only in non-thinking mode and never writes thinking blocks, so you do not need to set enable_thinking. It also reads and writes text only; Qwen's newer Qwen3.6 models add image input and optional thinking.
Which coding tools work with Qwen3-Coder-Next?
Qwen names Claude Code, Qwen Code, Qoder, Kilo, Trae and Cline, and its launch post shows it in OpenClaw and a browser-use agent. Tools that accept an OpenAI-compatible endpoint work once you serve it with vLLM or SGLang.
Our verdict
Qwen3-Coder-Next is still a quick, free coder for your own hardware, but it is no longer the Qwen model to start with.
Its 3B active parameters make it fast and users trust it for guided edits, yet newer Qwen models plan better and Qwen Cloud is retiring its hosted API.
- Skip it for
- Anyone who needs a hosted API, image input or an agent that works from a loose spec.
- Check first
- Make sure your machine can hold the 48 GB 4-bit build before you download it.
 Laguna S 2.1

 Qwen3.8-27B
 KAT-Coder-Pro V2
 Rnj-1
 Mellum2
 Ornith-1.0