
What is NousCoder-14B?
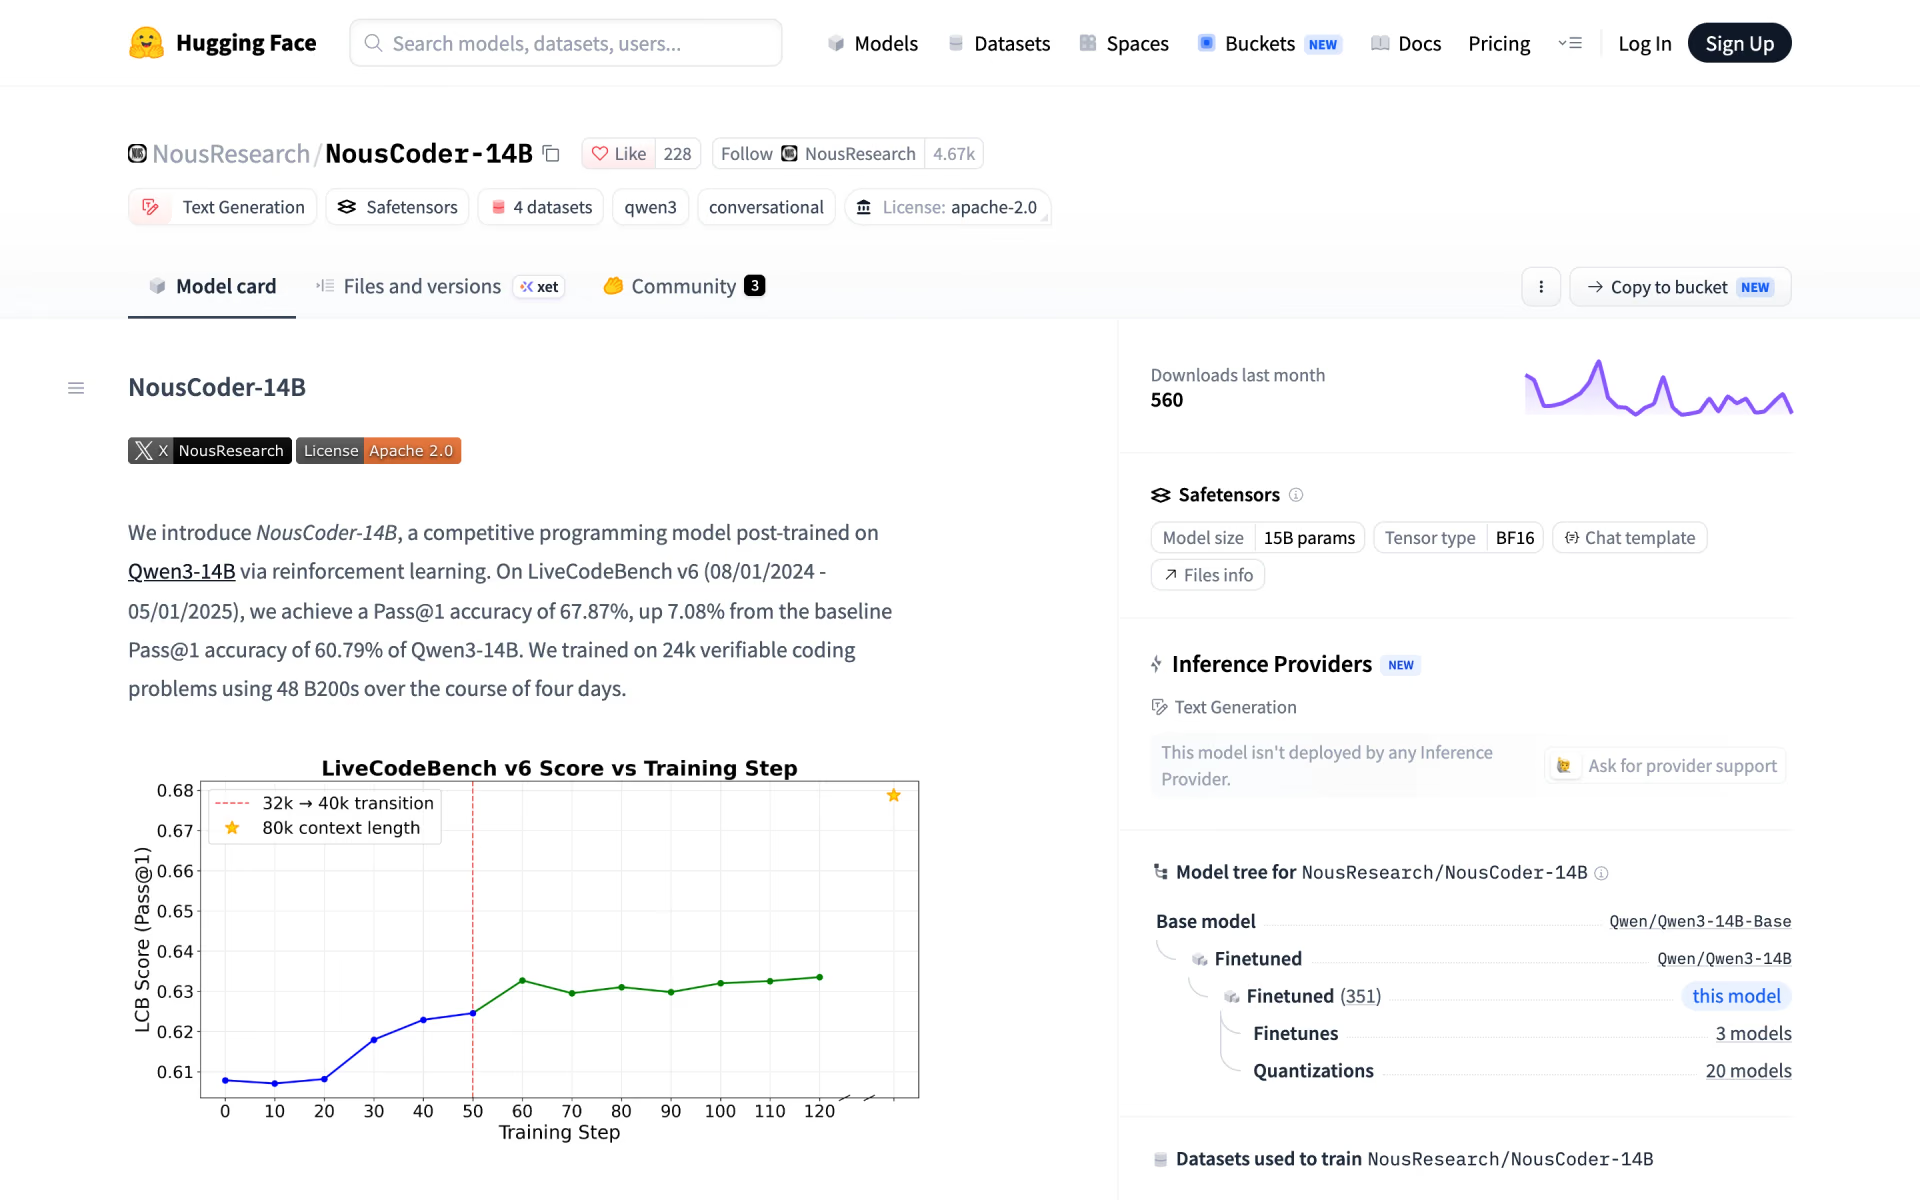
NousCoder-14B is Qwen3-14B post-trained by Nous Research with reinforcement learning on 24,000 verifiable contest problems. The model earned a reward only when its Python solution passed every test case within the time and memory limits. It reads and writes text, and its config stretches the context to 81,920 tokens with YaRN.
It is a research release rather than a product. Nous published the weights, the RL environment and the training logs, but runs no API for it. It is still available and Nous has not replaced it, yet unlike agentic coding models it was trained only on single-turn problems, not on tools or multi-step repo work.
What changed from Qwen3-14B?
Only the training: the architecture and size are the same, and RL on contest problems added about seven points on LiveCodeBench v6.
- Training
- Reinforcement learning on 24,000 verifiable contest problems, run for four days on 48 B200 GPUs.
- Score
- LiveCodeBench v6 Pass@1 rose from 60.79% to 67.87% at an 81,920-token context, and to 63.35% at the base 40,960.
- Context
- 81,920 tokens through YaRN, twice the base model's native 40,960.
- Focus
- Reinforcement learning covered only Python solutions to competitive programming problems.
Who is NousCoder-14B best for?
NousCoder-14B is best for people who solve or study competitive programming problems in Python and for researchers who want a reproducible RL recipe for code.
Competitive programming practice
It was trained only on contest problems judged by input and output test cases under time and memory limits, like those on Codeforces.
RL researchers
Nous released the RL environment, the training logs and the objectives it compared, so you can reproduce the run or build on it.
Local use on one GPU
It is a dense 14B model with 29.5 GB of BF16 weights, small enough for a single data-centre GPU, with community quantized builds for smaller cards.
What's included with NousCoder-14B?
RL training on 24,000 verifiable problems, an 81,920-token context, a fully published training stack and Qwen3-compatible weights.
- RL on verifiable problems
- Trained on 24,000 problems where code only scored when it passed every test within 15 seconds and 4 GB of memory.
- Longer context
- YaRN doubles Qwen3-14B's 40,960 tokens to 81,920, which lifted its LiveCodeBench score by about four and a half points.
- Open training stack
- The RL environment sits in Nous's Atropos framework on GitHub, and the Weights & Biases training logs are public.
- Qwen3 architecture
- It keeps Qwen3-14B's architecture and chat format, so runtimes that load Qwen3 models can load it.
How much does NousCoder-14B cost?
NousCoder-14B is free: the Apache 2.0 weights download at no cost from Hugging Face, and Nous Research sells no API or paid plan for it.
- Apache 2.0 licence, commercial use allowed
- About 29.5 GB of BF16 weights on Hugging Face
- You pay only for your own hardware
Nous Research sells no API, subscription or paid tier for NousCoder-14B. It is not in the Nous Portal model catalog, and no Hugging Face inference provider serves it, so running it means your own GPU or a rented one. Full pricing on huggingface.co. We checked these prices on .
How do readers rate NousCoder-14B?
No one has rated NousCoder-14B yet. Be the first.
Sign in to rate. One rating per account.
NousCoder-14B pros and cons
It clearly beats its Qwen3-14B base on LiveCodeBench and is fully open, but it only knows single-turn Python contest problems and some users doubt the headline score.
Pros
- Lifts Qwen3-14B's LiveCodeBench v6 score from 60.79% to 67.87% Pass@1, by Nous's own measure.
- Fully open: the weights, the RL environment, the hyperparameters and the training logs are all public, so the run can be reproduced.
- Small enough for one GPU at 29.5 GB in BF16, and free to use commercially under Apache 2.0.
Cons
- Several Reddit users doubt the headline score because Nous tracked LiveCodeBench during training, and its write-up says it picked checkpoints on that benchmark.
- Trained only on Python contest problems in single turns, so it is not built for other languages, tool use or multi-file repo work; users flagged the missing language details at launch.
- Nous says its answers quickly fill the context window, and wrong answers run longer than right ones.
- No hosted API from Nous or any Hugging Face inference provider, so you need your own hardware.
Is NousCoder-14B open source?
Yes. NousCoder-14B's code is public under the Apache 2.0 licence, so you can run it on your own server.
What are the best NousCoder-14B alternatives?
NousCoder-14B is an open source alternative to Gemini 3.1 Deep Think. DeepSeek-V3.2-Speciale and Nomos 1 do the same job and are open source too.
 Gemini 3.1 Deep ThinkPaid
Parallel reasoning for maths, science, engineering and code, on Google AI Ultra.
 DeepSeek-V3.2-SpecialeOpen Source
DeepSeek's high-compute V3.2 variant for hard math and coding problems, released as open weights.
 Nomos 1Open Source
Nous Research's open maths reasoning model.
 North Mini CodeOpen Source
Choose it when you want a model that works inside coding agents and edits real repositories; it is trained for tool use with a 256K context, where NousCoder-14B only solves single contest problems.
 Qwen3.6-27BOpen Source
Choose it when you need an everyday coding model that also reads images and long files; it has a 262K context against NousCoder's 81,920 tokens, under the same Apache 2.0 licence.
 Falcon H1R 7BFree
Choose it when GPU memory is tight; its weights are about 15 GB, half NousCoder's size, with a 262K context and maths reasoning too, though under TII's Falcon licence rather than Apache 2.0.
Questions about NousCoder-14B
What is NousCoder-14B?
NousCoder-14B is Nous Research's free, Apache 2.0 open-weight model for competitive programming, made by training Qwen3-14B with reinforcement learning to solve contest problems in Python.
Who is NousCoder-14B for?
NousCoder-14B is best for people who solve or study competitive programming problems in Python and for researchers who want a reproducible RL recipe for code.
Is NousCoder-14B free?
Yes. NousCoder-14B has a free Open weights plan: apache 2.0 licence, commercial use allowed.
Is NousCoder-14B open source?
Yes. NousCoder-14B's code is public under the Apache 2.0 licence, so you can run it on your own server.
What are the best NousCoder-14B alternatives?
The closest alternatives on Recaply are Gemini 3.1 Deep Think, DeepSeek-V3.2-Speciale, Nomos 1, North Mini Code, Qwen3.6-27B and Falcon H1R 7B.
Where can I try NousCoder-14B?
On its official website, huggingface.co.
Is NousCoder-14B good for everyday coding or coding agents?
Not really. Nous trained it only on single-turn competitive programming problems with Python answers, and lists multi-turn training as future work. For repo edits, tool calls or other languages, a model trained for agentic coding is the better fit.
Is there a NousCoder-14B API?
No. Nous Research does not host NousCoder-14B, it is not in the Nous Portal model catalog, and no Hugging Face inference provider serves it. You download the Apache 2.0 weights and run them on your own or rented hardware.
What hardware do I need to run NousCoder-14B?
The BF16 weights take about 29.5 GB, so at full precision you need a GPU with more than 30 GB of memory, plus room for its long outputs. Community quantized builds on Hugging Face shrink it for smaller cards.
Can I reproduce NousCoder-14B's training?
Yes. Nous published the RL environment in its Atropos framework, its training logs and hyperparameters, and it trained on the same 24,000-problem dataset as DeepCoder-14B. The full run took four days on 48 B200 GPUs.
Our verdict
NousCoder-14B is a useful open research model for Python contest problems, not an everyday coding assistant.
Nous lifted Qwen3-14B from 60.79% to 67.87% on LiveCodeBench v6 and published every part of the recipe, but the model only learned single-turn contest problems.
- Skip it for
- You want an assistant that edits repositories, calls tools or writes languages other than Python.
- Check first
- Test it on problems outside LiveCodeBench first, since Nous picked its checkpoints on that benchmark.

 Qwen3.8-27B

 MiniMax M2.1
 GLM-4.7
 MiMo-V2.5-Pro

 GLM-5.1

 SWE-2